FindBugs-driven bughunting in legacy projects

I have been working on a >100k lines legacy project for a while now. We have to juggle customer requests, bug fixes and refactoring so it is hard to improve the quality and employ new techniques or tools while keeping the software running and the clients happy. Initially there were no unit tests and most of the code had a gigantic cyclomatic complexity. Over the course of time we managed to put the system under continuous integration, employed quite some unit tests and analyzed code “hotspots” and our progress with crap4j.

Normally we get bug reports from our userbase or have to test manually to find bugs. A few weeks ago I tried a new approach to bughunting in legacy projects using FindBugs. Many of you surely know this useful tool, so I just want to describe my experiences in that project using FindBugs. Many of the bugs may be in parts of the application which are seldom used or only appear in hard to reproduce circumstances. First a short list of what I encountered and how I dealt with it.

Interesting found bugs in the project

  • There was a calculation using an integer division but returning a double. So the actual computation result was wrong but yet the error would have been hard to catch because people rarely recalculate results of a computer. When writing the test associated to the bugfix I found a StackOverFlowError too!
  • There were quite some null dereferences found, often in contructs like
     if (s == null && s.length() == 0)
     

    instead of

    if (s == null || s.length() == 0)
    

    which could be simplified or rewritten anyway. Sometimes there were possibilities for null dereferences on some paths despite of several null checks in the code.

  • Many performance bugs which may or may not have an effect on overall performance of the system like: new String(), new Integer(12), string concatenation across loops, inefficient usage of java.util.Map.keySet() instead of java.util.Map.entrySet() etc.
  • Some dead stores of local variables and statements without effect which could be thrown away or be corrected to do the intended things.

Things you may want to ignore

There are of course some bugs that you may ignore for now because you know that it is a common pattern in the team and abuse and thus errors are extremely unlikely. I, for example, opted to ignore some dozens of “may expose internal representation” found bugs regarding arrays in interfaces or accessibly via getters because it is a common pattern on the team not to tamper existing arrays as they are seen as immutable by the team members. It would have taken too much time to fix all those without that much of a benefit.

You may opt to ignore the performance bugs too but they are usually easy to fix.

Tips

  • If you have many foundbugs, fix the easy ones to be able to see the important ones more easily.
  • Ignore certain bug categories for now, fix them later, when you stumble upon them.
  • Concentrate on the ones that lead to wrong behaviour and crashes of your application.
  • Try to reproduce the problem with unit test and then fix the code whenever feasible! Tests are great to expose the bug and fix it without unwanted regressions!
  • Many bugs appear in places which need refactoring anyway so here is your chance to catch several flies at once.

Conclusion

With FindBugs you can find common programming errors sprinkled across the whole application in places where you probably would not have looked for years. It can help you to understand some common patterns of your team members and help you all to improve your code quality. Sometimes it even finds some hard to spot errors like the integer computation or null dereferences on certain paths. This is even more true in entangled legacy projects without proper test coverage.
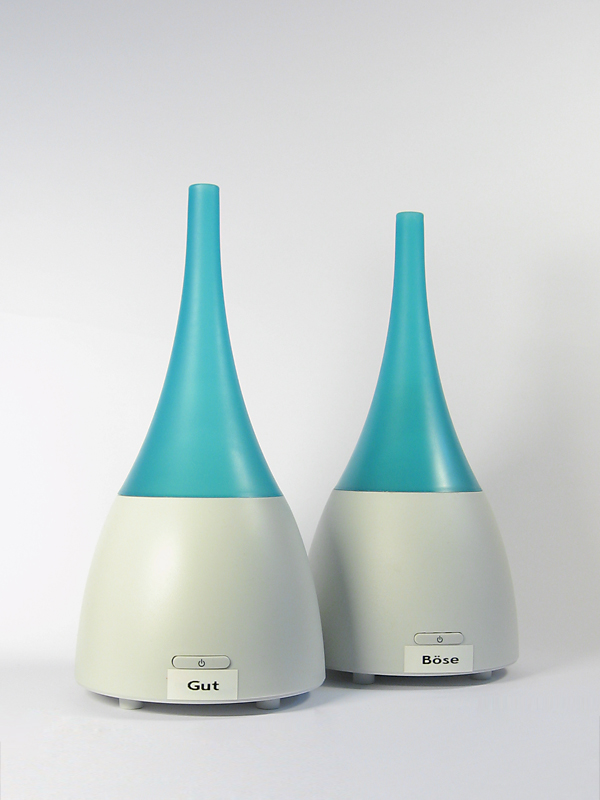
Smell if it’s well

Ever wondered how a code smell would taste like? We chose it to be like vanilla. Our latest extreme feedback device scents our office air depending on code quality.

We at the Softwareschneiderei are constantly searching for ways to gather feedback from our projects. We get feedback from our customers and their users, but we also get feedback directly from the code, be it through test results or code analysis. A great way to make your code speak for itself is to provide it some Extreme Feedback Devices (XFD).

IntroduciIMG_0574_smellng the Smell-O-Mat

One thing we always wanted to have was “code smells” that really smell for themselves. When we ran across an ultrasonic humidifier that can produce room-wide smells by dispensing essential oils, we found the right device for this feedback. We bought two humidifiers and labeled them “good” and “evil”. The hardest part was to find a smell everybody relates to “evil”, but won’t distract you too much from your work. Whenever our code analysis finds a new real code smell, the “evil” humidifier is turned on for some minutes. If an existing code smell is fixed, we get the “good” smell.

The effects

We do not produce code smells all too often. But once in a while, it happens. And this incident can now be perceived throughout the day just by breathing. On the other hand, fixing old smells is a source of refreshing air. Whenever the office atmosphere needs replenishment, all you have to do is to fix some code smells in our large code base (they do get rare!). Of course, most junior developers just open a window for that.

We chose grapefruit being our “good” smell, so our work area tastes mostly limony now instead of just “developer’s thoughts”, a fragrance that yet has to bottled.

The technical solution

Technically, the integration of the two humidifiers with our reporting infrastructure was very easy. Every XFD is controlled by an IRC bot that understands certain commands suitable for the device and hangs around at our central IRC server. As an humidifier only understands “on” and “off”, it could be controlled just like the ONOZ! lamp. We connected the humidifiers to a remote controlled power supply, switched it on and let the bot control the supply.

Our reporting infrastructure forwards its results to an aggregation software that interprets the numbers and produces IRC commands for the device bots. All of this is done with a combination of website scraping (Hudson as our continuous integration server has a wonderful XML API) and IRC messaging.

The history of XFD so far

Over the last years, we gathered XFDs for almost every human sense. We have visual effects, audible feedback using speech synthesis and even bought an USB rocket launcher for forced feedback needs. With the Smell-O-Mat, we can now deal with smelling, too.
The last human sense we have to address is tasting. Plans for the “coffee salter” were impeded by our sense of humanity. We keep searching.


Read more about our Extreme Feedback Devices:

A guide through the swamp – The CrapMap

Locate your crappy methods quickly with this treemap visualization tool for Crap4J report data.

One of the most useful metrics to us in the Softwareschneiderei is “CRAP”. For java, it is calculated by the Crap4J tool and provided as an HTML report. The report gives you a rough idea whats going on in your project, but to really know what’s up, you need to look closer.

A closer look on crap

The Crap4J tool spits out lots of numbers, especially for larger projects. But from these numbers, you can’t easily tell some important questions like:

  • Are there regions (packages, classes) with lots more crap than others?
  • What are those regions?

So we thought about the problem and found it to be solvable by data visualization.

Enter CrapMap

If you need to use advanced data visualization techniques, there is a very helpful project called prefuse (which has a successor named flare for web applications). It provides an exhaustive API to visualize nearly everything the way you want to. We wanted our crap statistics drawn in a treemap. A treemap is a bunch of boxes, crammed together by a clever layouting strategy, each one representing data, for example by its size or color.

The CrapMap is a treemap where every box represents a method. The size gives you a hint of the method’s complexity, the color indicates its crappyness. Method boxes reside inside their classes’ boxes which reside in package boxes. That way, the treemap represents your code structure.

A picture worth a thousand numbers

crapmap1

This is a screenshot of the CrapMap in action. You see a medium sized project with few crap methods (less than one percent). Each red rectangle is a crappy method, each green one is an acceptable method regarding its complexity.

Adding interaction

You can quickly identify your biggest problem (in terms of complexity) by selecting it with your mouse. All necessary data about this method is shown in the bottom section of the window. The overall data of the project is shown in the top section.

If you want to answer some more obscure questions about your methods, try the search box in the lower right corner. The CrapMap comes with a search engine using your methods’ names.

Using CrapMap on your project

CrapMap is a java swing application, meant for desktop usage. To visualize your own project, you need the report.xml data file of it from Crap4J. Start the CrapMap application and load the report.xml using the “open file” dialog that shows up. That’s all.

In the near future, CrapMap will be hosted on dev.java.net (crapmap.dev.java.net). Right now, it’s only available as a binary executable from our download server (1MB download size). When you unzip the archive, double-click the crapmap.jar to start the application. CrapMap requires Java6 to be installed.

Show your project

We would be pleased to see your CrapMap. Make a screenshot, upload it and leave a comment containing the link to the image.

Easy code inspection using QDox

Spend five minutes and inspect your code for the aspect you always wanted to know using the QDox project.

Copyright by http://www.clipartof.com/So, you’ve inspected your Java code in any possible way, using Findbugs, Checkstyle, PMD, Crap4J and many other tools. You know every number by heart and keep a sharp eye on its trend. But what about some simple questions you might ask yourself about your project, like:

  • How many instance variables aren’t final?
  • Are there any setXYZ()-methods without any parameter?
  • Which classes have more than one constructor?

Each of this question isn’t of much relevance to the project, but its answer might be crucial in one specific situation.

Using QDox for throw-away tooling

QDox is a fine little project making steady progress in being a very intuitive Java code structure inspection API. It’s got a footprint of just one JAR (less than 200k) you need to add to your project and one class you need to remember as a starting point. Everything else can be learnt on the fly, using the code completion feature of your favorite IDE.

Let’s answer the first question of our list by printing out all the names of all instance variables that aren’t final. I’m assuming you call this class in your project’s root directory.

public class NonFinalFinder {
    public static void main(String[] args) {
         File sourceFolder = new File(".");
         JavaDocBuilder parser = new JavaDocBuilder();
         builder.addSourceTree(sourceFolder);
         JavaClass[] javaClasses = parser.getClasses();
         for (JavaClass javaClass : javaClasses) {
             JavaField[] fields = javaClass.getFields();
             for (JavaField javaField : fields) {
                 if (!javaField.isFinal()) {
                     System.out.println("Field "
                       + javaField.getName()
                       + " of class "
                       + javaClass.getFullyQualifiedName()
                       + " is not final.");
                }
            }
        }
    }
}

The QDox parser is called JavaDocBuilder for historical reasons. It takes a directory through addSourceTree() and parses all the java files it finds in there recursively. That’s all you need to program to gain access to your code structure.

In our example, we descend into the code hierarchy using the parser.getClasses() method. From the JavaClass objects, we retrieve their JavaFields and ask each one if it’s final, printing out its name otherwise.

Praising QDox

The code needed to answer our example question is seven lines in essence. Once you navigate through your code structure, the QDox API is self-explanatory. You only need to remember the first two lines of code to get started.

The QDox project had a long quiet period in the past while making the jump to the Java 5 language spec. Today, it’s a very active project published under the Apache 2.0 license. The developers add features nearly every day, making it a perfect choice for your next five-minute throw-away tool.

What’s your tool idea?

Tell me about your code specific aspect you always wanted to know. What would an implementation using QDox look like?