Recap of the Schneide Dev Brunch 2014-12-14

If you couldn’t attend the Schneide Dev Brunch at 14nd of December 2014, here is a summary of the main topics.

brunch64-borderedIn mid-december, we held another Schneide Dev Brunch, a regular brunch on a sunday, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was well-attended and we didn’t even think about using the roof garden (cold and rainy). There were lots of topics and chatter. As always, this recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

International brunch

We tried to establish a video conference with a guest from San Francisco and had tried the technical implementation beforehands. But we didn’t succeed, mostly because of a sudden christmas party on the USA side. So we can’t really say if the brunch character is preserved even if you join us in the middle of the (local) night.

How much inheritance do you use?

One question was how inheritance is used in the initial development of systems. Is it a pre-planned design feature or something that helps to resolve difficult programming situations in an ad-hoc manner? How deep are the inheritance levels?
The main response was that inheritance is seldom used upfront. The initial implementations are mostly free of class hierarchies. Inheritance is often used after the fact to extract abstractions (or generalizations) from the code. The hierarchies mostly grow “upwards” from the concrete level to abstract superclasses.
Another use case of inheritance is the handling of special cases with further specialization through subclasses. The initial class is modified just enough to enable proper insertion of the new code in its own subclass.
A third use case of inheritance, upfront this time, was proposed in regard of the domain model. Behavioural typing is a common motivation for the usage of inheritance in the model, as contrasted to the technical usage of inheritance to solve non-domain problems. In the domain level, inheritance resembling a “behaves-like” relation can be the most powerful expression of actual connections between types.

Book review “Analysis patterns”

The discussion about inheritance led to questions about domain models and their expression through formal notation. An example about accounts resulted in a short review of the book “Analysis Patterns”, written by Martin Fowler in 1999. The book introduces its own notation for models to be able to express the interrelations without being dragged down into the implementation level. UML isn’t suited as it’s a notation from the technical domain. Overall, the book seems to be mostly overlooked and under-appreciated. It contains a lot of valueable wisdom in the area of domain analysis, an activity that has to be done upfront of any larger project. This “upfront activity” characteristics might have led to it being ignored in most agile processes. The book is a perfect companion to Eric Evan’s “Domain-Driven Design”.

Book review “Agile!”

Another book review of this brunch was a deep review of Bertrand Meyer’s book “Agile! The Good, the Hype and the Ugly”. The book is the written opinion of Mr. Meyer in regard of all current agile processes and very polarizing as such – he does state his points clearly. But it’s also a very well-researched assessment of nearly all aspects of agile software development. You might want to argue with certain conclusions, but you’ll have to admit that Mr. Meyer knows what he’s talking about and got his facts right (even if his temper shines through sometimes). This book is the perfect companion to all the major agile books you’ve read. It serves as a counter-balance to the dogmatic views that sometimes come across. And it serves as a (albeit personal) rating of all agile practices, a gold mine for every project manager out there. the book itself is rather short with some reiterations (you’ll get the major points, even if you skip some pages) and written in an informal tone, so it’s an easy read as long as you’re neutral towards the topic.
When we reviewed the rating of agile practices on a big whiteboard, ranging from ugly to brilliant, it didn’t took long until discussions started. If nothing else, this book will help you review your practices and beliefs.

Embedded Agile on the rise

The next topic was related to agile software development, too. In the large field of embedded software development, adoption of agile practices lagged behind substantially. This has many reasons, of which we discussed a few, but the more interesting trend was that this changes. While there is still a considerable lack of literature for embedded software overall, the number of publications advocating modifications to the agile processes to fit the intricacies of embedded software development is steadily increasing.
A similar trend can be observed in the user experience community (think: user interface designers), termed “lean UX“.

Mobile game presentation

A long-awaited highlight of this brunch was the presentation of a mobile platforms game under development by one attendee. It’s a cool-looking Jump-and-Run game in the tradition of Super Mario, with lots of gimmicks and innovative effects. The best part of the presentation was the gameplay, controlled by the developer from behind the device, upside down and with live commentary. The game is developed in a platform-agnostic manner using several frameworks and suitable coding habits. Right now, it’s in its final phase of development and will be released soon. I don’t want to spoil too much beforehands and invite Martin (the author) to insert a comment below with links leading to more information.

A change in the Dev Brunch mechanics

The last topic on our agenda was a short review of the Dev Brunch series in the last years. In 2013, we introduced the extra “workshop events” that were adapted to the “game nights” in 2014. We want to return to more serious topics in 2015 and revive the workshops. Attendees (and future ones) are invited to make suggestions which workshop they would like to see. The Dev Brunch itself will be formalized further by introducing a steady pace of bi-monthly dates.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.
The four rules of data safety

I tried to translate the four rules of gun safety to the task of data validation in order to formulate a behavioural framework of improved input safety.

firefly-gunOne of the most dangerous objects to handle is guns. No wonder there are strict and understandable rules how to handle them safely. The Canadians have The Four Firearm ACTS, but for this blog entry, I will cite the Four Rules stated by Captain Ira L. Reeves right before the first world war and restated by Colonel Jeff Cooper:

  1. All guns are always loaded
  2. Never let the muzzle (the business end of a gun) cover anything you are not willing to destroy
  3. Keep you finger off the trigger until your sights are on the target
  4. Be sure of your target and what is beyond it

Even if you accidentally break one rule (for example, rule 3 is often blatantly disobeyed on television), there are still enough precautions in place to keep you (and everybody around you) relatively safe. The rules are meant to instill a certain amount of respect for the gun into the owner so that offloading of responsibility isn’t possible any more, as in the line “I know this gun is unloaded, so it’s probably mighty fun to point it at somebody”.

The guns of software development

In software development, the most dangerous objects we can handle is user-created data or inputs. To mitigate the risks we take when we accept inputs from our users (and most software would be pretty useless otherwise), we have the concept of validation: Before anything other may happen with the data, it needs to be validated, meaning “proved to be free of danger”. Improper input validation is so prevalent in software development that it has its own CWE number (CWE-20) and ranked number 1 on the Top 25 list of “most dangerous programming errors”.

There are some concepts ready to help us tackle this task. The most promising is the Taint checking that treats all input as dangerous and therefore unworthy of further usage unless proven otherwise. Taint checking reminds you of validation, but not how to validate and isn’t available in most programming languages, unfortunately. What we need is a language agnostic set of rules that shape our behaviour in a way that we can’t make the most common mistakes of validation. It seems that gun owners have tried the same and succeeded. So Let’s formulate our Four Rules of data safety, inspired by the gun rules.

Our four rules

  1. All data always contains malicious aspects
  2. Never accept input for modules you cannot afford to have hacked
  3. Leave input data alone until you actually want to use it
  4. Be sure what aspects to validate and how to do it properly

This is just a starting ground for discussion, let’s call it the first version of the Four Rules. Here is my motivation for each rule:

All data always contains malicious aspects

Most users of most systems are in no way harmful. But if they attempt to harm a system, it better stands prepared. Problem is, even with a thorough validation in your current context, there is always the possibility that your attacker plays a rail shot, entering the system here, but causing damage somewhere else. A good example of this practice were images with Javascript code in their metadata. An adequate validation of uploaded images would check for a valid image format, but don’t mind the “dead content” in the meta tags. A browser would later discover the Javascript and execute it – a classic cross-site scripting attack. Never treat any data as fully validated. If you know that your particular code is vulnerable to a specific threat, let’s say a zero value in a variable used as a divisor, validate once more against this threat. This practice is also contained in the idea of Defensive programming.

Never accept input for modules you cannot afford to have hacked

Behind this rule lies a simple truth: Everything that can be hacked will be hacked, given enough time. The only protection against any hack is no access at all (like in “some air between network cable and network card”). If for example you run a certificate authority and absolutely cannot risk losing your secret private key, the machine using this key must not be connected to any network. If your database contains data much too valuable to be “stolen”, the database shouldn’t be accessible directly – and all access need to be validated beforehand. You need to think about a pragmatic compromise for your scenario when following this rule, but you’ve always been warned.

Leave input data alone until you actually want to use it

This was the most difficult rule for me to decide on. The rationale is that even the slightest bit of validation is actually usage of the input. Given enough knowledge about the validation, an attacker could possibly attack the system by abusing weaknesses in the validation itself (see rule 1 for inspiration). Any contact with input data is dangerous, even when it happens with the best intentions. The downside is that you won’t have a stronghold security architecture, where a mighty wall separates the danger zone from friendly territory (or tainted from cleaned data). Remember that even persisting the input data is using it in some form.

Be sure what aspects to validate and how to do it properly

If the time has come to use the input and to validate it right before, you need to think deep about the threats you want to eliminate. Just like with guns, where real bullets (as opposed by “television bullets”) won’t stop at the shooter’s convenience, your validation has consequences beyond an immediate gain of security. A common error is the rushed countermeasure, when you think of a specific threat and immediately try to abolish it. Take your time and think deep! For example, if your users can enter way too high values, it’s of no use to constrain the input field length, because direct web requests and notations like “1E9” are still possible. But converting an input string to a number to check its value might not be the smartest idea, too. Not long ago, you could crash nearly every application by entering a certain “number of death”. Following this rule requires experience and lots of reading, learning and thinking. And even then, there’s always somebody smarter than you, so ultimately, you should plan your system under the impression of rule 2.

As stated, this is just a starting point to try to formulate rules for data validation that provide a behaviour framework that avoids the most common mistakes and pitfalls. I’m highly interested to hear your thoughts about this topic. Please leave a comment below – but be gentle with the comment validation algorithm.

Programming mistakes of my past self – Part I

As a Clean Code Developer, I often reflect on my work. This led me to investigate the mistakes I made in the past and to analyze them in detail. Here are three mistakes I really made, why I did them and how to fix them.

One thing that fascinates me about software development is the fact that we aren’t done yet as a profession, we just barely started. New paradigms, programming languages and concepts, even new technologies are invented, discovered and refined at every moment. Add a personal journey of skill acquisition and improvement, and it’s enough for a fulfilled professional life. But as a Clean Code Developer, I often pause and reflect – on me, my work and why I do it in this particular way. I’m aware that I’m on a perpetuating process of self-improvement, always better than yesterday (hopefully), but never as good as I want to be. Reflecting the changes and transformations I made in the past helps me to understand changes in the present or even in the future. So this is a blog entry about mistakes, probably embarrassing ones, that I really made and didn’t think anything was wrong at some point in my professional career.

But before I make my confessions, please keep this disclaimer in mind: Most of these mistakes, I made in the ancient days of my schooling and early steps. I’ve come a long way since, read a ton of books, wrote several big software systems and switched programming languages several times. I didn’t write this to make fun of my past self, but to gather (and provide) insight into the mind of an apprentice and how he rationalizes aspects of software development that seem out of place or even funny to more experienced developers. The purpose is to be more aware of more recent sketchy rationalizations, not to laugh about how stupid I was – even if I’ve probably been stupid.

No indentation

Origin:
Yes, really. I started my professional/academic career with strictly left-aligned code and no sense of the value of indentation. It just seemed meaningless “additional effort” to me. Let me explain why while you laugh. I started my career with BASIC, and after years of tinkering around and finally reading books about it (this was long before the world wide web, mind you!), discovered that I could circumvent the limitations of the runtime by directly PEEKing and POKEing to the memory. Essentially, I began to write machine code in BASIC. As soon as I had this figured out, my language of choice was now assembler, because why drill holes into BASIC every time I wanted to do something meaningful (like changing the VGA palette mid-frame to have more than 256 colours available). Years of assembler programming followed. Assembler isn’t like any other programming language, it’s more of a halfway de-scrambled machine code and as such has no higher concepts like loops or if-else statements. This is more or less like every program in assembler looks like:

push    20h
call    401010
add     esp,4
xor     eax,eax
ret

You’ve probably already guessed where this leads to: In assembler, all scoping/blocking of code has to be done by the programmer in his head. There was no value in indentation because there was no hierarchy of statements and everything was on the same level of (nearly non-existent) abstraction. I got used to the level of attention you have to maintain to keep track of your code. So when I started programming in Java during my study, the hard nut to crack was object orientation, not the simple task of understanding code without indentation.

Mistake:
It didn’t occur to me that my code was hard to understand for other readers (e.g. my tutor) without proper formatting. Code was cryptic and hard to understand, so what? I didn’t regard obfuscation as a problem, but was proud to be “one of the few” who could actually understand what was going on.

Remedy:
I’ve come a long way since. Nearly two decades in application development taught me to write, structure and format my code as clearly as I can – and always add some extra effort into clarity. Good code is readable, and readable code is understandable by virtually everybody, not only a chosen few. Indentation is a very important tool to lead the reader (and yourself) through your program. It’s no coincidence that the first rule of the Object Calisthenics deals with indentation.

Single return functions

Origin:
This one also roots in my first years of programming BASIC and assembler. In assembler, you never think about anything other than one clear exit from a subroutine, because you need to restore all register context before the jump back by hand. In BASIC, there was that lingering danger that you couldn’t break free from a loop or a routine too early because the interpreter would mess up its internal context. If you were inside a loop and left the subroutine by “Exit Sub” command, the loop context was still present and ready to bite you.
In short, everything else but a clearly cut exit strategy from a function was dangerous and error prone. The additional code infrastructure needed to maintain such a programming style, e.g. additional local variables and blown-up conditionals were necessary costs in my book. To be honest, I didn’t even think about any alternative, because in my reality, you needed to care about your stack content even in BASIC.

Mistake:
I didn’t think about ways to minimize my effort in micromanaging the computer. In my defense, this would have totally alienated assembler programming for me. Assembler is all about micromanagement and CPU nursery. It didn’t occur to me that my value system (stack handling is coder’s work) limited my ability to express the goals of a function (instead of its minutiae).

Remedy:
Great recapulations of most arguments against single return functions can be found in the C2 wiki and various other internet sources like this great question on stackexchange.com
I dropped this style quickly when finally wrapping my head around the fact that the Java VM handles all memory including the stack for me and doesn’t want me to interfere (or “optimize”). Once freed from micromanagement issues, you can adapt your stylistic choice to the matter at hand and write code that supports your problem domain instead of adhering to limitations from the technical domain.

Special naming conventions for interfaces

Origin:
One of the hardest topics in object-oriented programming for me was the concept of “abstract” classes or even those mysterious interfaces. What’s the use of an interface anyway when it doesn’t even contain code? It seemed like additional work without benefit for me. And with a programming style that stores everything in primitive data types (where else?), interfaces just don’t cut it. So I adopted a style that marks everything dubious with extra prefixes to move it out of the way when it comes to naming. Let’s say I want to program a class that represents a user (class User), but are somehow forced or tempted to create an interface for it? Just name it IUser! It’s such a no-brainer that interfaces didn’t require any effort in their creation. And while we are at it, let’s name all abstract classes AbstractXYZ, because that’s much better than the alternative – to name the concrete class XYZImpl (disclaimer: both options are flawed). Cool, a new concept in Java 5 were Enums, let’s prefix them with “big E” so we can always tell them apart. And while we are at it, every exception should end with… well, I think you can guess.

Mistake:
I’m happy to announce that I never fell in the Hungarian notation trap. But that doesn’t serve as an excuse for the type name prefix mess I maintained longer than I’m willing to admit. The mistake was to overburden type names with implementation details and let the technical domain leak into my type system.

Remedy:
One day, I decided to cut it out and began to eliminate prefixes and suffixes in type names. It started a process of discoveries, insights and new possibilities much like in the case of single return functions. And the process isn’t even finished yet. Just recently, Kevlin Henney came along and gave me another push forward on my journey to really good type names (Seven ineffective coding habits of many programmers). As a reminder: The compiler doesn’t care about your names. Most readers don’t care about the actual technical realization of a type as long as they know what the type is for in the problem domain. Even you yourself don’t care about prefixes in the name once the name-finding phase is past. Let me phrase this facetious: “Equal naming rules for all types of types!”

Only the beginning

These three examples are only the beginning of a whole list of mistakes, misconceptions and plain falsities of mine. I hope you’ll see the intention behind the confession, not only the amusing part of self-revelation. Try it on yourself! Think back to your early days as a software developer and write down the funny things you worked with and were proud of. Then try to fit them into the scheme: How did you start doing it? Why exactly was it a mistake (in the long run)? And what was the aspect that drove you away from it? How did you fix your mistake?

I would love to hear and learn from your mistakes, too.

Snowflakes are a bad sign

Snowflake servers are brittle and expensive. Treating hardware like cattle instead of pets is one strategy to overcome the snowflake syndrome. Here are some strategies to foster this mindset.

snowflakeFirst, allow me a bad joke: If you enter your server room and find real snowflakes, it might be a sign that your air conditioning is over-ambitious. But even if you just enter your server room, you probably see some snowflakes, but in the metaphorical sense.

Snowflake servers

Snowflakes are servers with an unique layout. I cannot say it better than Martin Fowler two years ago in his Bliki posting SnowflakeServer, but I’m trying to add some insights and more current tools. The term probably originates in the motto that everybody is a “precious unique snowflake”. This holds true for humans and animals, but not for machines. Let’s examine how a snowflake is born. Imagine that in the beginning, all servers are the same: standard hardware, a default operating system and nothing more. You pick one server to host a special application and adjust the hardware accordingly. Now you already have an hardware snowflake – not the worst thing, but you better document your rationale behind the adjustment in an accessible way – a wiki page specifically for that server perhaps. Because sooner or later, that machine will fail (or become hopelessly obsolete) and needs to be replaced – with adequate hardware. Without your documentation, you’ll have to remember why the old machine had that specific layout – and if it was sufficient. I’ve seen the “ancient server” anti-pattern much too often: A dusted machine, buzzing like an asthmatic pensioner in the last corner of the server room, and nobody was allowed near. Because there are no spare parts (VESA local bus isn’t supported anymore), if one part fails, the whole system is doomed – operating system and software included. Entire organizations rely on the readiness for duty of one hardware assembly – and almost always a crude one.

Server as cattle

The ancient server happens more likely when you treat your servers like pets. This is the crucial mental switch you’ll have to make: servers are cattle, not pets. They have numbers, not names. They can be monitored, upgraded and fostered, but at the end of the day, they serve a clearly defined business case and deserve no emotional investment of the owner. If a pet gets hurt, you take it to the veterinary and cure it. If cattle gets sick, you call the veterinary to make sure it’s not contagious and then replace the affected individuals – to cure them would be more expensive. Pets live as long as they can, cattle has a dacattlete of expiry. And our cattle (servers) really isn’t sentient, so stop treating it like pets.

Strategies to run a ranch

Our current answer to make the transition from pet zoo to cattle ranch without significantly increasing the amount of metal in our server room can be boiled down to three strategies:

  • Virtualize the logical machines. Instead of working on “real metal machines”, more and more of our services run inside virtual machines. This allows for a clearer separation of concerns (one duty per machine) and keeps the emotional commitment towards the machine low. Currently, we use VirtualBox and Docker for this task. Both are easy to set up and fulfill their task well.
  • Remove the names from real metal machines. We really number our real machines now. Giving clever names to virtual machines is still possible, but not necessary: they are probably only accessed using DNS aliases that specify their use, like “projectX-database” or “projectY-webserver”. We even choose the computer cases for our machines accordingly to separate the pets (unique cases) from cattle (uniform cases).
  • Specify the machine. The virtualized hardware must be described and explained (e.g. why this particular machine needs twice the normal RAM ration). Currently, we use Vagrant to specify the hardware and operating system of our virtual machines. The specifications are stored in a version controlled repository, so there is a place where most of our server infrastructure is described in a deployable fashion. Even more, all necessary third-party software products are specified, too. Imagine a todo list of what to install and prepare, like the one you’ve handed over to your admin in the past, but automatically executable. We currently use Ansible for our configuration management because it has very low requirements for the target platform itself and has a low learning curve.

Applying these three strategies, every (logical) machine in our server room should be reproduceable. They are still individuals, specifically tailored for their jobs, but completely specified and virtualized. The real metal machines only run the bare minimum of software necessary to host the logical machines. None of the machines promote emotional attachment – they are tools for their job.

Data is snow

One important insight is that persistent data will turn your machine into a snowflake over time (we use the term as a verb: “data will snowflake your machine”). You will become emotionally and financially attached to this data – otherwise, there is no need to persist it in the first place. We don’t have a panacea here yet. You probably want to use a database and a sophisticated backup strategy here. Just make sure that the presence of precious data on it doesn’t obscure your stance towards the machine. You want to keep the data and still be able to throw the machine away.

Don’t stop at machines

We are software developers, so we cannot deny that the concept of snowflaking is very helpful for our own projects, too. Every dependency that we can bring with us during deployment (called “self-containment” or “batteries included” in our slang) is one less thing of “snowflaking” the target machine. Every piece of infrastructure (real, virtualized or purely conceptual) we implicitly rely on (like valid certificates, SSH keys or passwords and database locations) will snowflake the target machine and should be treated accordingly: documented, specified and automated. If you hot-fix a production server, it’s definitely a huge snowflaking action that needs to be at least carefully documented. You can’t avoid snowflaking completely, but strive to mimize the manual amount of it and then sanitize the automated part.

Snowflaking is a concept

We’ve found the term of “snowflaking” very useful to transport the necessity and value in documenting, specifying and automating everything that doesn’t happen on a developer machine (and even there, the build process is fully automated). Snowflaked enviroments tend to be expensive in maintainance and brittle in operations. The effort to mitigate the effects of snowflaking pays off very soon and is highly reuseable. But even more powerful is the change in the mindset as soon as the concept of “snowflaking” is understood. It’s a short term for a broad range of strategies and values/beliefs. It’s a powerful and scalable concept.

We’d love to hear your experiences

You’ve probably experimented with various tools and concepts to manage your servers, too. What were your experiences and insights? Add a comment below, we are looking forward to your input.

The power of analysis

A short story about the power of good analysis. Thinking in terms of the problem domain is a key ingredient.

Quite some years ago, I heard a story about the power of analysis that happened even deeper in the past. Its moral holds true until today, though. It’s the insight that to fully analyse a particular challenge or task, you have to think outside your own box. Let’s hear the story before we analyse it:

The problem

A small company for sensor technology usually solved customer problems like distance measurement without contact or gas mixture control. The team was informed about all the latest sensors and trained to come up with solutions even to really challenging tasks. This lead to a word of mouth recommendation for a new customer that promptly described his problem.

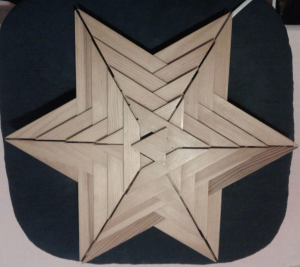
christmas-star-lamp-smallThe customer ran a workshop for physically handicapped people that mostly worked with wood and produced a wide variety of products that got sold on various markets. One product was the Christmas lamp in shape of a star. It proved to be a best-seller and had a good economic ratio. At least it could have, if only the rejects rate would be lower. To assemble the lamp from little wooden laths was difficult for skilled workers and even harder for skilled handicapped workers. The main difficulty was to glue the laths in just the right angle to result in the desired star shape. The customer needed some set-up of sensors that would indicate to the worker when the angle was right. He imagined something like a cheap navigation system that would yell/display “left” and “right” until the angle was “correct”.

The solution finding

The team accepted the task and started the creative solution process that lasted several days of thinking, doodling, researching and scribbling. Then, the team gathered for a solution finding session. A multitude of ideas were presented and almost instantly rejected. From laser distance measurement over acoustic ultrasonic sensors to camera-based image evaluation, everything cool and remotely feasible was presented and rejected because nothing had an even remote chance to succeed outside of laboratory settings. Not one approach survived the applicability check. The team was devastated and returned to the creative phase, if not as reckless as the first time.

The solution

A few days later, the second solution finding session had only a few new ideas, none standing a chance. Finally, a student spoke up: “This isn’t a problem that should be solved with sensors!”. Well, this was a bold sentence in a team of sensor technologists. The student explained: “The real problem is the placement of the small laths, not the correct angle itself. Even if we build a sensor that can reliably indicate right and wrong angles, it would just tell the worker that whatever he tries, he won’t get it right. These workers don’t need supervision, they need assistance. No sensor is going to deliver that.” The team was baffled. The student went on: “I thought about a solution that will assist the worker during the assembly, but it’s nothing we will get rich with. A simple mould in the right shape, perhaps non-adhering to the glue they use for the wood, would let them produce one half of the lamp. Glue two of those halves together and everything fits. No need for batteries even.”

christmas-lamp-star-sideWhen the sensor technology company proposed this solution to the customer, he laughed loud and long. It was the most elegant and inexpensive solution he never thought of. It was exactly what was needed. It worked perfectly from the first prototypes onward. The Christmas lamp rejects rate dwindled to almost zero instantly. In short: perfect score. Just that the sensor technology company wouldn’t earn anything with maintenance or improvements was a minor drawback.

Good analysis

This story is my illustrative material when I have to explain what good analysis is. Let’s take a look at the bafflement of the team: They had all started their solution finding with the premise that this was a problem inside their area of expertise. Even the customer said so. Good analysis works out the real nature of a problem regardless of what anybody says about it. This includes any description given by the customer or even the wood workers in charge of the actual work. Good analysis finds a solution that fits the problem, not the field of expertise of the analyst.

Analysis is the process of thinking in terms of the problem space. In this story, an important part of the analysis was already done by the customer: Most of the rejects have wrong angles, so we need to make sure the angles are correct and we need a machine to tell us, because apparently the workers themselves can’t. The machine needs sensors, so lets assign a sensor company on the task. This was the initial premise that nobody except the student questioned. And this was half of the analysis that nobody bothered to repeat. You cannot really understand the problem if you begin your thinking mid-flight.

Applying good analysis

It’s easy to tell a story (even if it really happened) and derive insights from it. It’s much harder to apply these insights in the own work. The crucial step is to fully understand the actual problem that should be solved (in the story: correct justification instead of correct angle). The next step is to incorporate the value system of the customer: if I alter some key characteristics of the solution, will it still serve the customer’s actual needs? In the story: A cheap aluminium mould serves the customer even better than some expensive fancy machine. The mould can be duplicated nearly infinitely, the machine probably not. The mould is grasped instantly, the machine needs instructions. The mould keeps working long after the machine ran out of battery. The mould assists, the machine merely scolds.

If, after thoroughly working on these two steps, the solution lies still inside your field of expertise, you can proceed to design the solution. You’ve just left the analysis process to concentrate on one possible solution. That’s all right, but remember to return to the earliest steps of analysis when you get stuck. Designing a solution for a falsely analysed premise almost always leads nowhere in the long run.

Recap of the Schneide Dev Brunch 2014-08-31

If you couldn’t attend the Schneide Dev Brunch at 31nd of August 2014, here is a summary of the main topics.

brunch64-borderedYesterday, we held another Schneide Dev Brunch, a regular brunch on a sunday, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was well-attended this time but the weather didn’t allow for an outside session. There were lots of topics and chatter. As always, this recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Docker – the new (hot) kid in town

Docker is the hottest topic in software commissioning this year. It’s a lightweight virtualization technology, except that you don’t obtain full virtual machines. It’s somewhere between a full virtual machine and a simple chroot (change root). And it’s still not recommended for production usage, but is already in action in this role in many organizations.
We talked about the magic of git and the UnionFS that lay beneath the surface, the ease of migration and disposal and even the relative painlessness to run it on Windows. I can earnestly say that Docker is the technology that everyone will have had a look at before the year is over. We at the Softwareschneiderei run an internal Docker workshop in September to make sure this statement holds true for us.

Git – the genius guy with issues

The discussion changed over to Git, the distributed version control system that supports every versioning scheme you can think of but won’t help you if you entangle yourself in the tripwires of your good intentions. Especially the surrounding tooling was of interest. Our attendees had experience with SmartGit and Sourcetree, both capable of awesome dangerous stuff like partial commmits and excessive branching. We discovered a lot of different work styles with Git and can agree that Git supports them all.
When we mentioned code review tools, we discovered a widespread suspiciousness of heavy-handed approaches like Gerrit. There seems to be an underlying motivational tendency to utilize reviews to foster a culture of command and control. On a technical level, Gerrit probably messes with your branching strategy in a non-pleasant way.

Teamwork – the pathological killer

We had a long and deep discussion about teamwork, liability and conflicts. I cannot reiterate everything, but give a few pointers how the discussion went. There is a common litmus test about shared responsibility – the “hold the line” mindset. Every big problem is a problem of the whole team, not the poor guy that caused it. If your ONOZ lamp lights up and nobody cares because “they didn’t commit anything recently”, you just learned something about your team.
Conflicts are inevitable in every group of people larger than one. We talked about team dynamics and how most conflicts grow over long periods only to erupt in a sudden and painful way. We worked out that most people aren’t aware of their own behaviour and cannot act “better”, even if they were. We learned about the technique of self-distancing to gain insights about one’s own feelings and emotional drive. Two books got mentioned that may support this area: “How to Cure a Fanatic” by Amos Oz and “On Liberty” from John Stuart Mill. Just a disclaimer: the discussion was long and the books most likely don’t match the few headlines mentioned here exactly.

Code Contracts – the potential love affair

An observation of one attendee was a starting point for the next topic: (unit) tests as a mean for spot checks don’t exactly lead to the goal of full confidence over the code. The explicit declaration of invariants and subsequent verification of those invariants seem to be more likely to fulfil the confidence-giving role.
Turns out, another attendee just happened to be part of a discussion on “next generation verification tools” and invariant checking frameworks were one major topic. Especially the library Code Contracts from Microsoft showed impressive potential to really be beneficial in a day-to-day setting. Neat features like continuous verification in the IDE and automatic (smart) correction proposals makes this approach really stand out. This video and this live presentation will provide more information.

While this works well in the “easy” area of VM-based languages like C#, the classical C/C++ ecosystem proves to be a tougher nut to crack. The common approach is to limit the scope of the tools to the area covered by LLVM, a widespread intermediate representation of source code.

Somehow, we came across the book titles “The Economics of Software Quality” by Capers Jones, which provides a treasure of statistical evidence about what might work in software development (or not). Another relatively new and controversial book is “Agile! The Good, the Hype and the Ugly” from Bertrand Meyer. We are looking forward to discuss them in future brunches.

Visual Studio – the merchant nobody likes but everybody visits

One attendee asked about realistic alternatives to Visual Studio for C++ development. Turns out, there aren’t many, at least not free of charge. Most editors and IDEs aren’t particularly bad, but lack the “everything already in the box” effect that Visual Studio provides for Windows-/Microsoft-only development. The main favorites were Sublime Text with clang plugin, Orwell Dev-C++ (the fork from Bloodshed C++), Eclipse CDT (if the code assist failure isn’t important), Code::Blocks and Codelite. Of course, the classics like vim or emacs (with highly personalized plugins and setup) were mentioned, too. KDevelop and XCode were non-Windows platform-based alternatives, too.

Stinky Board – the nerdy doormat

One attendee experiments with input devices that might improve the interaction with computers. The Stinky Board is a foot-controlled device with four switches that act like additional keys. In comparison to other foot switches, it’s very sturdy. The main use case from our attendee are keys that you need to keep pressed for their effect, like “sprint” or “track enemy” in computer games. In a work scenario, there are fewer of these situations. The additional buttons may serve for actions that are needed relatively infrequently, but regularly – like “run project”.

This presentation produced a lot of new suggestions, like the Bragi smart headphones, which include sensors for head gestures. Imagine you shaking your head for “undo change” or nod for “run tests” – while listening to your fanciest tunes (you might want to refrain from headbanging then). A very interesting attempt to combine mouse, keyboard and joystick is the “King’s Assembly“, a weird two-piece device that’s just too cool not to mention. We are looking forward to hear more from it.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The high number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.

Don’t ever not avoid negative logic

If you want to be nice to people with a challenged relationship with boolean logic, try to avoid negative formulations and negations.

I start this post with a confession: I’m not able to discern true from false. I wasn’t born with this inability, it got worse over time. The first time I knew I have this problem was in driver’s school when my teacher told me that most people cannot switch from forward to backward drive and still tell left from right. Left and right are the same to me ever since, even in forward motion. When I was taught boolean logic, my inability spread from “left and right” to “true and false” and led to funny results in some tests, especially multiple choice questions with negative statements. But my guess is that I’m not alone with this problem.

No negations

So I’m probably a little bit over-sensitive about this topic, but that should only make the point clearer: Don’t obscure your (boolean) statement with unnecessary layers of negation. See? I just did it, too. Let me rephrase: Always state your boolean logic without negation, if possible.

It’s really easy for us super-clever programmers to juggle several dozen variables in our head and evaluate any boolean statement on the fly by reading it once – regardless of parenthesis. Well, until it’s not. The thing about boolean logic is that you can’t be “unsure”. It’s only ever “true” or “false”, and just by wild guessing, you will be right about it half the time – try that with basic numerical algebra! So even if the statement looks daunting, you have a fifty-fifty chance of success.

Careful crafting

For me (and probably all people with “boolean disability”, as I call it), every boolean statement is a challenge. So you can be sure that I put maximum effort in succeeding. I write my statements carefully and with great emphasis on clarity (this blog post only covers one aspect). I re-read them several times, sometimes aloud (to my imaginary rubber duck). I thoroughly test them – most statements are factored into their own method to achieve direct testability. And I try them out before committing. Still, there is a valid chance that my boolean disability didn’t magically disappear when I wrote my unit tests and I happily asserted that the statement always has to decide the right things in the wrong way.

By painful introspection about the real nature of my boolean disability, I discovered a great easement: If a statement doesn’t flip everything on its head by negation or negative formulation, I can actually follow through most of the time. Let me rephrase for clarity: If a statement uses negation, it is hard for me to follow. And I guess everyone has a personal limit:

ow_owl

A workaround

The workaround for my boolean disability is really easy: Express the statement like it really was meant in the first place. Express it without “plot twist”. Instead of

if (!string.isEmpty())

try something like

if (string.hasContent())

Disclaimer: I know that the Java SDK (still) doesn’t provide this method. It was just an example.

A real-life example

A real-life example that caused us some troubles can be found in the otherwise excellent Greenmail plugin for Grails. In the configuration, you can set the property

greenmail.disabled = true

to disable the mail server that otherwise would start automatically. The positive formulation would be

greenmail.enabled = false

To tell the full story: The negated formulation was probably chosen to simplify the plugin’s implementation in Groovy. The side effect of this short-cut is that you can’t state

greenmail.disabled = false

and be sure that it will start the mail server. In fact, it won’t. As a developer challenged by boolean logic, this issue gave me nightmares.

The three-state trap

Using this rule as a guideline for boolean statements will also prohibit that you fall into the “three-state trap”. Imagine a Person object with the method

boolean isOlderThan(Person other)

But you want to know if a person is younger than another, so you just negate the result:

if (!personA.isOlderThan(personB))

just to be clear, following the rule of “no negations”, you would’ve written:

if (personA.isYoungerThan(personB))

which isn’t quite the same! If both persons are of equal age (the “third state”), the negated statement returns true (if I evaluated it correct!), whereas the last statement gives the correct answer (false – not younger).

Use as a guideline

Don’t get me wrong: Avoiding negations isn’t always possible or the best available option. This isn’t a law, it’s a guideline or a rule of thumb. And just because some complex boolean statement is free of negations doesn’t make it acceptable automatically. It’s just a tiny step towards pain-free boolean statements. And that’s a bad thing… NOT.

Finally: return considered harmful

No wonder nobody wants to write explicit return statements anymore. They are more dangerous than you might think.

Ok, calm down already – I’m not going to take your return statement away. It’s a nice little statement that gets rarer and rarer,  mostly because many modern languages allow for implicit return values, e.g. in Scala, everything is an expression and the last expression of a method is its return value – except when it isn’t. You dont need to write an explicit return statement anymore, so our laziness takes over and we omit it.

And I’m not argueing that a finally block is a bad thing – quite the contrary. Even in the age of try-with-resources and autoclose closures, a well-crafted finally block is a beautiful piece of code at its right place.

But put the two together and you’ve got a recipe for desaster, at least in Java (try it in your language of choice with care). Let’s have a look at code:

public void doSomething() {
    try {
        throw new Error("drama!");
    } finally {
        // dispose resources here
    }
}

Ok, I could have spared you the drama of an Error and just thrown a RuntimeException (or a declared and checked Exception), but it’ll soon illustrate the effect all the better.

First, the code does exactly what it should: if you call the method, you’ll get to catch an Error and all resources that were used inside the method are cleaned up right before you catch it. And since the method has no return value, you don’t miss out there.

But what if I want to give one of those endangered return statements a new home and insert it into the finally block?

public void doSomething() {
    try {
        throw new Error("drama!");
    } finally {
        // dispose resources here
        return;
    }
}

Not much has changed. I’m still not missing any return value and the Error still gets thrown. The resources are cleaned up quite as thorough as before, but something important has changed: You won’t ever see the Error. You won’t catch it because it gets eaten by that return statement at the end of the finally block.

So in short: return statements are hungry little beasts that will eat your Throwables if you corral them inside a finally block.

No wonder nobody wants to have them in their code if they behave like that.

Oh, and rest assured that you will be warned: All modern IDEs will point you to the inevitable desaster waiting to happen, if only with a compiler warning.

But where do Throwables go when they got eaten? Good question. They don’t show up on any UncaughtExceptionHandler, they don’t even stay in memory. Probably, they just are digested, never to be seen again.

If you don’t regard return statements as a little more dangerous now, you probably also raise switch-statements for fun.

Recap of the Schneide Dev Brunch 2014-06-22

If you couldn’t attend the Schneide Dev Brunch at 22nd of June, here is a summary of the main topics.

brunch64-borderedYesterday, we held another Schneide Dev Brunch at last. The Dev Brunch is a regular brunch on a sunday, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was smaller this time, but we held the last brunch only three weeks ago. We had bright sunny weather and used our roof garden, but hurdled in the shadows. There were lots of topics and chatter. As always, this recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Student again – from full employee to university

One of our attendees worked as a full-time software developer in the recent years and decided to study again. He told us about the practical challenges of an employee turned student:

  • The bureaucracy at universities is highly developed and not on your side. It takes days to accomplish the tiniest step towards matriculation.
  • To listen again. In the developer world, two hours of highly concentrated programming is satisfying, but two hours of concentrated listening to somebody who tells the important stuff only once is very hard. You are allowed to doze off (just like in big meetings), but it won’t do you no good.
  • Higher-level mathematics. Suddenly, all that stuff about fourier transformation and matrices is very important again.
  • Running on a lower gear. It seems like heaven to replace a 40h work week with a 20h study week, but the irregular pace (one day no lectures, one day lectures around the clock, etc.) will take its toll.
  • Self-organization. Good developers are of course self-organized and know what to do: work on the most important issues in your issue tracker/todo list. But university will not write issues for you and you are the one to fill the todo list. We joked that a “master’s student JIRA” would actually be a good idea.

It was a very entertaining talk and we digressed lots of times. Let’s have a look at some artifacts we came across during our discussion:

  • There seems to be a growing influence from military concepts on management. On book was specifically mentioned: Turn the ship around” by David Marquet.
  • “Bad work, good work and great work”. It’s a marketing video, but contains a message nonetheless. One practical advice is to not include “bad work knowledge” in your curriculum vitae, even if you have expertise in it. This minimizes the risk that your next job will contain a lot of “bad work” again.

The current state of JavaFX

Last year, JavaFX was aggressively marketed by Oracle as the next big thing in desktop UI. The claims and promises seem to finally be fulfilled. The combination of Java 8 and the latest JavaFX is especially joy-bringing. The JavaFX core is included in Java 8 and brings a lot of little but essential improvements. You can layout and design your graphical interfaces with a WYSIWYG editor and store it in XML-based layout files. These layouts are loaded, combined with custom logic and bound to custom data sources. The styling is based on a slightly outdated CSS dialect, but very powerful and done right in comparison to styling in past toolkit like Swing or SWT.

The best thing about JavaFX is that much less GUI code is needed for more pleasant user experiences. The toolkit feels alive and the details tell that the developers care and eat their own dogfood. Integration in the Eclipse IDE is enhanced by the e(fx)clipse project.

Our attendee has hands-on experience with Swing, SWT/JFace and JavaFX. If pressed to choose the technology for a new project, he would choose JavaFX anytime now.

Efficiency killers

We also traded tales about the most efficient efficiency killers in software development that we actually observed or endured:

  • Taking away notebooks and desktop computers and replacing them with zero clients – for developers that really need their multi-cores and gigabytes.
  • Restricting every employee to one (and only one!) computer. If you happen to choose a notebook, you probably don’t need that extra monitor, do you?
  • Installing a “privilege management” software. Basically, this software works like a firewall against user inputs. You want to install a new printer driver? It will be cheaper and faster to carve your text in stone slabs.
  • Fragmenting the company networks. This is actually a very good idea. You can have a wild-west style network for developers and a “privilege managed” one for management. It gets complicated when you need to cross the canyons everytime to get work done. Just imagine that your repository is behind a firewall and you need a clearance every time you want to commit/push.

Introduction to warfare

The last main topic was an overview of a self-study on warfare. And because the typical software developer won’t move whole armies around, it concentrated more on the principles and strategies of “common” warfare, which includes everyday conflicts as well as campaigns for a certain goal (e.g. establishing a technology). Three books serve as stepping stones:

  • The art of war” by Sun Tzu. The ancient classic book about warfare. There are probably a dozen different translations of the original chinese text, but they will only serve as a starter. This book alone will probably don’t give you deep insights, but you will come back to it often when you venture deeper into the mindset of warriors and generals.
  • Die Kunst der List” by Harro von Senger. This german book describes the political and rhetorical battle moves that are often used in everyday life. These so-called strategems can be identified and parried if you know about them. Most of us can react to some strategems by learnt lessons, but it certainly helps to be keen about the rest of them, too.
  • The 33 Strategies of War” by Robert Greene. This book doesn’t mess around. It is part of the “immoral series” of books about topics that don’t get discussed in this clarity often. You’ll learn much about strategies, their actual application in history (not only on the battlefield, but on movie sets, offices and political stages) and how to counter them. The book has a lot of content and many ideas and concepts to think about. And it contains an exhaustive list of literature to continue reading.

Is TDD dead?

We continued our discussion about the debate around David Heinemeier Hansson’s frontal attack on the hype around Test Driven Development. There were some new insights and an improved understanding about the manyfold contents of the hangout discussions.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The high number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.
Recap of the Schneide Dev Brunch 2014-06-01

If you couldn’t attend the Schneide Dev Brunch at 1st of June, here is a summary of the main topics.

brunch64-borderedYesterday, we held another Schneide Dev Brunch at last. The Dev Brunch is a regular brunch on a sunday, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was very well-attended this time. We had bright sunny weather and used our roof garden to catch some sunrays. There were lots of topics and chatter. As always, this recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Home office in another time zone

One of our attendees is preparing to leave Germany for at least one year to work in another timezone one the same projects. He gave a quick overview about the setup and some considerations. The team is used to distributed, multi-timezone work, but will now span the whole scala of it. We are eager to have a first-hand report about how it all plays out and sad that we will not see him for quite a time in person. (Personal note: I will miss the developer beer meetings we held infrequently)

XP 2014 conference in Rome

Another one of our attendees just came back from the XP 2014 conference in Rome, still hungover. She reported a lot of impressions and single bits of insights impromptu and will work up a more refined talk for the next brunch. One thing that seems like a really good idea is the “Stop Work Authority Card”. Basically, it’s a card you can hold up like a referee in a sports match to clearly state that the safety of some of your most valueable assets is compromised or risking to be. You have the obligation to play the card if you perceive such a threat and the (temporary) authority to remove it or have it removed.

The idea of “safety” (in non-hazardous or friendly) was a big theme at the conference. The claim that “safety is the prerequisite of excellence” stood out.

The XP 2014 conference was a small one, but visited by insiders from all over the world. It certainly sparked a lot of ideas and food for thought. We are looking forward for the report at the next Dev Brunch.

Is TDD dead?

A most recent discussion we at the Softwareschneiderei follow with great interest is the debate around David Heinemeier Hansson’s frontal attack on the hype around Test Driven Development. There are lots of blog posts to read, some better, some not so much. But an highlight is probably the video chat series between Kent Beck (inventor of TDD), Martin Fowler (general loudmouth, here in a rather quiet role as a moderator) and David Heinemeier Hansson (general firestarter). And while the topic is hot and the discussion fresh, we soon deviated from the main questions and explored the state of art how knowledge and experience is transported in our profession. We concluded that while we all dislike populism, it’s an effective tool to transport messages (with the downside of losing nuances on the way).

Continuous improvement

One attendee asked about good ways to improve his skill and craft. Besides the obvious answers (sleep less, train more, read a lot), there were quite a few ideas. One source of inspiration could be “Jiro Dreams of Sushi”, a documentary movie about a famous sushi master and his quest to perfect the art of sushi (yes, the little snacks that are delicious even without mastery). The concept of “better every day, but never good enough” was identified to be prone to perfectionism, a trait often found in masters of their field, but probably not the most economically sound one. The author of this blog post wrote about his approach to professional passion three years ago.

Radical table

We agreed to consider our little discussion group “the radical table” because we don’t shy away from argueing in the extremes to get our messages across. This all was mentioned in good spirits and without personal insults. But if you read about the “radical table manifesto” some point in the future, don’t be surprised. It might include a plea to Uncle Bob to never give up his style to deliver keynotes and talks even if we don’t attend it twice.

Start-up software tools

In the end of the brunch, we split into several smaller groups to discuss more specific topics of personal interest. I can’t report for the talks I didn’t attend, but joined a discussion about recommendable and necessary tools for a software development start-up company. Some tools that were given included OpenERP, JIRA (including the whole Atlassian portfolio), FogBugz, Microsoft Office 365 and CAS Genesis World.

One controversial topic was the importance of integration (as in “one tool for everything”) versus requirement matching (as in “does exactly what we want”). Related was the topic of “plan ahead” versus “change tools mid-flight”. If you have experience with these questions, please leave a comment.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The high number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.