Recap of the Schneide Dev Brunch 2015-08-09

If you couldn’t attend the Schneide Dev Brunch at 9th of August 2015, here is a summary of the main topics.

brunch64-borderedTwo weeks ago, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. So if you bring a software-related topic along with your food, everyone has something to share. The brunch was well attented this time with enough stuff to talk about. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

News on Docker

Docker is the hottest topic among developers and operators in 2015. No wonder we started chatting about it the minute we sat down. There are currently two interesting platform projects that provide runtime services for docker: Tutum (commercial) and Rancher (open source). We all noted the names and will check them out. The next interesting fact was that Docker is programmed in the Go language. The team probably one day decided to give it a go.

Air Conditioning

We all experienced the hot spell this summer and observed that work in the traditional sense is impossible beyond 30° Celsius. Why there are still so few air conditioned offices in our region is beyond our grasp. Especially since it’s possible to power the air condition system with green electricity and let sun-power deal with the problem that, well, the sun brought us. In 2015 alone, there are at minimum two work weeks lost to the heat. The productivity gain from cooling should outweigh the costs.

License Management

We talked about how different organisations deal with the challenge of software license management. Nearly every big company has a tool that does essentially the same license management but has its own cool name. Other than that, bad license management is such a great productivity killer that even air conditioning wouldn’t offset it.

Windows 10

Even if we are largely operation system agnostic, the release of Windows 10 is hot news. A few of our participants already tried it and concluded that “it’s another Windows”. A rather confusing aspect is the split system settings. And you have to abdicate the Cortana assistant if you want to avoid the data gathering.

Patch Management

A rather depressing topic was the discussion about security patches. I just repeat two highlights: A substantial number of servers on the internet are still vulnerable to the heartbleed attack. And if a car manufacturer starts a big recall campaign with cost-free replacements, less than 10 percent of the entitled cars are actually fixed on average. These explicitely includes safety-critical issues. That shouldn’t excuse us as an industry for our own shortcomings and it’s not reassuring to see that other industries face the same problems.

Self-Driving Cars

We disgressed on the future hype topic of self-driving cars. I can’t reiterate the complete discussion, but we agreed that those cars will hit the streets within the next ten years. The first use case will be freight transports, because the cargo doesn’t mind if the driver is absent and efficiency matters a lot in logistics. Plus, machines don’t need breaks. Ok, those were enough puns on the topic. Sorry.

Tests on Interfaces

An interesting question was how to build tests that can ensure a class or interface contract. Much like regression tests for recently broken functionality, compatibility tests should deal with backward compatibility issues in the interface. Turns out, the Eclipse foundation gave the topic some thoughts and came up with an exhaustive list of aspects to check. There are even some tools that might come in handy if you want to compare two versions of an API.

API Design

When the topic of API Design came up, some veterans of the Schneide Events immediately mentioned the API Design Fest we held in November 2013 to get our noses bloody on API design. Well, bleed we did. The most important take-away from the Fest was that if you plan to publish an API that can endure some years in production while being enhanced and improved, you just shouldn’t do it. Really, don’t do it, it’s probably a bad idea and you lack the required skill without even knowing it. If you want to know, participate or even host an API Design Fest.

And if you happen to design a web-based API, you might abandon backward compatibility by offering several distinct “versions” of APIs of a service. The version is included in the API URL, and acts more like a name than a version. This will ease your burden a bit. A nice reference resource might also be the PayPal API style guide.

Let’s just agree that API design is really hard and should not be done until it’s clear you don’t suffer from Dunning-Kruger effect symptoms too much.

Performance Tests

We talked about the most effective setup of performance tests. There were a lot of ideas and we cornerstoned the topic around this:

  • There was a nearly heroic effort from the Eclipse development team to measure their IDE performance, especially to compare different versions of the IDE. The Eclipse Test & Performance Tools Platform (TPTP) was (as in: discontinued) a toolkit of interesting approaches to the topic. The IDE itself was measured by performance fingerprints like this example from 2011. As far as we know, all those things ceased to exist.
  • At the last Java Forum Stuttgart, there was a talk about performance testing from an experienced tester that loved to give specific advice. The slides can be viewed online in german language (well, not really, but the talk was).
  • The book Release It! has a lot of insights to this topic. It’s one of the bigger books on the pragmatic bookshelf.
  • The engineers at NetFlix actually did a lot of thinking about the topic. They came up with Hystrix, a resilience library, aimed to make it easier to prevent complete system blackouts. They also came up with Chaos Monkey, a service that makes it easier to have a complete system blackout. If we can say anything about NetFlix, it is that they definitely approach their problems from the right angle.

Company Culture

Leaking over from the previous topic about effective performance-related measures, we talked about different company cultures, especially in regard to a centralized human resources departments and works council (german: Betriebsrat). We agreed that it is very difficult to maintain a certain culture and continued growth. We also agreed that culture trickles down from top management.

OpenGL

The last topic on this Dev Brunch was about the rendering of text or single characters in OpenGL. By using signed distance fields, you can render text more crisp and still only use cheap computation instructions. There is a paper from Valve on the topic that highlights the benefits and gives a list of additional reading. It’s always cool to learn about something simple that actually improves things.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.
A small example of domain analysis

One thing I’ve learned a lot about in recent years is domain analysis and domain modeling. Every once in a while, an isolated piece of code or a separable concept shows me just how much I’ve missed out all the years before. A few weeks ago, I came across such an example and want to share the experience and insight. It’s a story about domain exploration with heightened degree of difficulty – another programmer had analyzed it before and written code that I should replace. But first, let’s talk about the domain.

The domain

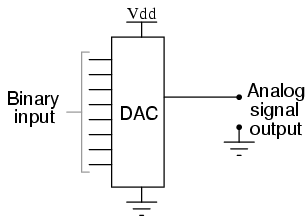
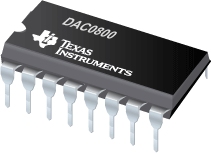
04250The project consisted of a machine control software that receives commands and alters the state of a complex electronic circuitry accordingly. The circuitry consists of several digital-to-analog converters (DAC), among other parts. We will concentrate on the DACs in this story. In case you don’t know what a DAC is, let me explain. Imagine a little integrated circuit (IC), the black bug-like electronic parts on a circuit board. On one side, you provide it a digital number in binary representation and on the other side, you’ll get an analog voltage that represents your number. Let’s say you drive a 8-bit DAC and give it a digital zero, the output will be zero volt. If you give the same DAC the number 255, it will output the maximum possible voltage. This voltage is given by the “reference voltage” pin and is usually tied to 5 V in traditional TTL logic circuits. If you drive a 12-bit DAC, the zero will still yield 0 V, while the 255 will now only yield about 0,3 V because the maximum digital number is now 4095. So the resolution of a DAC, given in bits, is a big deal for the driver.

DAC0800How exactly you have to provide that digital number, what additional signals need to be set or cleared to really get the analog voltage is up to the specific type of DAC. So this is the part of behaviour that should be encapsulated inside a DAC class. The rest of the software should only be able to change the digital number using a method on a particular DAC object. That’s our modeling task.

The original implementation

My job was not to develop the machine control software from scratch, but re-engineer it from existing sources. The code is written in plain C by an electronics technician, and it really shows. For our DAC driver, there was a function that took one argument – an integer value that will be written to the DAC. If the client code was lazy enough to not check the bounds of the DAC, you would see all kinds of overflow effects. It worked, but only if the client code knew about the resolution of the DAC and checked the bounds. One task the machine control software needed to do was to translate the command parameters that were given in millivolts to the correct integer number to feed it into the DAC and receive the desired millivolts at the analog output pin. This calculation, albeit not very complicated, was duplicated all over the place.


writeDAC(int value);

My original translation

One primary aspect when doing re-engineering work is not to assume too much and don’t change too many places at once. So my first translation was a method on the DAC objects requiring the exact integer value that should be written. The method would internally check for the valid value range because the object knows about the DAC resolution, while the client code should subsequently lose this knowledge. The original code translated nicely to this new structure and worked correctly, but I wasn’t happy with it. To provide the correct integer value, the client code needs to know about the DAC resolution and perform the calculation from millivolts to DAC value. Even if you centralize the calculation, there are still calls from everywhere to it.


dac.write(int value);

My first relevation

When I finally had translated all existing code, I knew that every single call to the DAC got their parameter in millivolts, but needed to set the DAC integer. Now I knew that the client code never cared about DAC integers at all, it cared about millivolts. If you find such a revelation, act on it – even just to see where it might lead you to. I acted and replaced the integer parameter of the write method on the DAC object with a voltage parameter. I created the Voltage domain type and had it expose factory methods to be easily created from millivolts that were represented by integers in the commands that the machine control software received. Now the client code only needed to create a Voltage object and pass it to the DAC to have that voltage show up at the analog output pin. The whole calculation and checking part happened inside the DAC object, where it belongs.


dac.write(Voltage required);

This version of the code was easy to read, easy to reason about and worked like a charm. It went into production and could be the end of the story.

The second insight

But the customer had other plans. He replaced parts of the original circuitry and upgraded most of the DACs on the way. Now there was only one type of DAC, but with additional amplifier functionality for some output pins (a typical DAC has several output pins that can be controlled by a pin address that is provided alongside the digital number). The code needed to drive the DACs, that were bound to 5 V reference voltage, but some channels would be amplified to double the voltage, providing a voltage range from 0 V to 10 V. If you want to set one of those channels to 5 V output voltage, you need to write half the maximum number to it. If the DAC has 12-bit resolution, you need to write 2047 (or 2048, depending on your rounding strategy) to it. Writing 4095 would yield 10 V on those channels.

Because the amplification isn’t part of the DAC itself, the DAC code shouldn’t know about it. This knowledge should be placed in a wrapper layer around the DAC objects, taking the voltage parameters from the client code and changing it according to the amplification of the channel. The client code would want to write 10 V, pass it to the wrapper layer that knows about the amplification and reduces it to 5 V, passing this to the DAC object that transforms it to the maximum reference voltage (5 V) that subsequently gets amplified to 10 V. This sounded so weird that I decided to review my domain analysis.

It dawned on me that the DAC domain never really cared about millivolts or voltages. Sure, the output will be a specific voltage, but it will be relative to your input in relation to the maximum value. The output voltage has the same percentage of the maximum value as the input value. It’s all about ratios. The DAC should always demand a percentage from the client code, not a voltage. This way, you can actually give it the ratio of anything and it will express this ratio as a voltage compared to the reference voltage. The DAC is defined by its core characteristics and the wrapper layer performs the translation from required voltage to percentage. In case of amplification, it is accounted for in this translation – the DAC never needs to know.


dac.write(Percentage required);

Expressiveness of the new concept

Now we can really describe in code what actually happens: A command arrives, requiring us to set a DAC channel to 8 volt. We create the voltage object for 8 volt and pass it on to the DAC wrapper layer. The layer knows about the 2x amplification and the reference voltage. It calculates that 8 volt will be 80% of the maximum DAC value (80% of 5 V being 4 V before and 8 V after amplification) and passes this information to the DAC object. The DAC object, being the only one to know its resolution, sets 0.8 * maximum_DAC_value to the required register and everything works.

The new concept of percentages decouples the voltage information from the DAC resolution information and keeps both informations where they belong. In fact, the DAC chip never really knows about the reference voltage, either – it’s the circuit around it that knows.

Conclusion

While it is easy to see why the first version with voltages as parameters has its charms, it isn’t modeling the reality accurately and therefor falls short when flexibility is required. The first version ties DAC resolution and reference voltage together when in fact the DAC chip only knows the resolution. You can operate the chip with any reference voltage within a valid range. By decoupling those informations and moving the knowledge about reference voltages outside the DAC object, I modeled the reality more accurate and every requirement finds its natural place. This “natural place finding” is what makes a good model useful for reasoning. In our case, the natural place for the reference voltage was outside the DAC in the wrapper layer. Finding a real name for the wrapper layer was easy, I called it “circuit board”.

Domain analysis is all about having the right abstractions for your model. Your model is suitable for your task when everything fits and falls into place nearly automatically. When names needn’t be found but kind of obtrude themselves from the real domain. The right model (for the given task) feels good and transports a lot of domain knowledge. And domain knowledge is the most treasurable knowledge for any developer.

Recap of the Schneide Dev Brunch 2015-06-14

If you couldn’t attend the Schneide Dev Brunch at 14th of June 2015, here is a summary of the main topics.

brunch64-borderedA week ago, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. So if you bring a software-related topic along with your food, everyone has something to share. The brunch was well attented this time with enough stuff to talk about. We probably digressed a little bit more than usual. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Distributed Secret Sharing

Ever thought about an online safe deposit box? A place where you can store a secret (like a password or a certificate) and have authorized others access it too, while nobody else can retrieve it even if the storage system containing the secret itself is compromised? Two participants of the Dev Brunch have developed DUSE, a secure secret sharing application that provides exactly what the name suggests: You can store your secrets without any cleartext transmission and have others read them, too. The application uses the Shamir’s Secret Sharing algorithm to implement the secret distribution.

The application itself is in a pre-production stage, but already really interesting and quite powerful. We discussed different security aspects and security levels intensily and concluded that DUSE is probably worth a thorough security audit.

Television series

A main topic of this brunch, even when it doesn’t relate as strong with software engineering, were good television series. Some mentioned series were “The Wire”, a rather non-dramatic police investigation series with unparalleled realism, the way too short science-fiction and western crossover “Firefly” that first featured the CGI-zoom shot and “True Detective”, a mystery-crime mini-series with similar realism attempts as The Wire. “Hannibal” was mentioned as a good psychological crime series with a drift into the darker regions of humankind (even darker than True Detective). And finally, while not as good, “Silicon Valley”, a series about the start-up mentality that predominates the, well, silicon valley. Every participant that has been to the silicon valley confirms that all series characters are stereotypes that can be met in reality, too. The key phrase is “to make the world a better place”.

Review of the cooperative study at DHBW

A nice coincidence of this Dev Brunch was that most participants studied at the Baden-Württemberg Cooperative State University (DHBW) in Karlsruhe, so we could exchange a lot of insights and opinions about this particular form of education. The DHBW is an unique mix of on-the-job training and academic lectures. Some participants gathered their bachelor’s degree at the DHBW and continued to study for their master’s degree at the Karlsruhe Institute of Technology (KIT). They reported unisono that the whole structure of studies changes a lot at the university. And, as could be expected from a master’s study, the level of intellectual requirement raises from advanced infotainment to thorough examination of knowledge. The school of thought that transpires all lectures also changes from “works in practice” to “needs to work according to theory, too”. We concluded that both forms of study are worth attending, even if for different audiences.

Job Interview

A short report of a successful job interview at an upcoming german start-up revealed that they use the Data Munging kata to test their applicants. It’s good to see that interviews for developer positions are more and more based on actual work exhibits and less on talk and self-marketing skills. The usage of well-known katas is both beneficial and disadvantageous. The applicant and the company benefit from realistical tasks, while the number of katas is limited, so you could still optimize your appearance for the interview.

Following personalities

We talked a bit about the notion of “following” distinguished personalities in different fields like politics or economics. To “follow” doesn’t mean buying every product or idolizing the person, but to inspect and analyze his or her behaviour, strategies and long-term goals. By doing this, you can learn from their success or failure and decide for yourself if you want to mimick the strategy or aim for similar goals. You just need to be sure to get the whole story. Oftentimes, a big personality maintains a public persona that might not exhibit all the necessary traits to fully understand why things played out as they did. The german business magazine Brand Eins or the english Offscreen magazine are good starting points to hear about inspiring personalities.

How much money is enough?

Another non-technical question that got quite a discussion going was the simple question “when did/do you know how much money is enough?”. I cannot repeat all the answers here, but there were a lot of thoughtful aspects. My personal definition is that you have enough money as soon as it gets replaced as the scarcest resource. The resource “time” (as in livetime) is a common candidate to be the replacement. As soon as you don’t think in money, but in time, you have enough money for your personal needs.

Basic mechanics of company steering

In the end, we talked about start-ups and business management. When asked, I explained the basic mechanics of my attempt to steer the Softwareschneiderei. I won’t go into much detail here, but things like the “estimated time of death” (ETOD) are very important instruments that give everyone in the company a quick feeling about our standings. As a company in the project business, we also have to consider the difference between “gliding flight projects” (with continuous reward) and “saw tooth projects” with delayed reward. This requires fundamentally different steering procedures as any product manufacturer would do. The key characteristic of my steering instruments is that they are directly understandable and highly visible.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.
Easy maintenance, not easy production

Imagine that you have to do critical changes in the source code, stressed, over-worked and under time pressure, without any recollection about your thoughts during development, lacking your familiar tools while your customer waits impatiently by your side. That’s when you are glad you prepared for this moment.

It is said that source code gets read a hundred times more often than it gets written. My experience confirms this circumstance, which leads to a principle of economic source code modifications: The first modification is almost for free, it’s the later ones that run up a bill. In order to achieve a low TCO (total cost of ownership), it’s sound advice to plan (and develop) for easy maintenance instead of easy production. This principle even has a fancy name: Keep It Simple, Stupid (KISS).

Origin of KISS

According to the english Wikipedia on the topic, the principle’s name was coined by an aircraft engineer named Kelly Johnson, who also designed the fastest jet plane of all time, the SR-71 “Blackbird”. The aircraft reached speeds of over Mach 3 and had an unmatched defensive armament: enough thrust to evade any confrontation. It would simply fly higher and/or faster than anything launched against it, like interceptor fighters or anti-air missiles. The Blackbird used construction material that was specifically invented for this plane and very expensive, so it definitely was no easy production. Sadly for this blog post, it wasn’t particularly easy to maintain, either. It usually leaked so much fuel that it had to be refueled directly after takeoff. The leaks were pragmatically designed that way and would seal themselves in flight. It’s quite an interesting plane.

Easy maintenance

Johnson once alledegly gave his engineers a bunch of tools and required that the aircraft under design must be repairable with only these tools, by an average mechanic in the field under combat conditions (e.g. stressed, exhausted and narrow timeframe). This is a wonderful concept that I regularly apply to my projects: Imagine that you are on-site with your customer, the most important functionality of your project just broke, resulting in a disastrous standstill of the whole facility and all you have is your sourcecode and the vi editor (or vim, if you’re non-hardcore like me). No internet, no IDE, no extensive documentation. Could you make meaningful changes to your project under these conditions? What needs to be changed to make your life easier in such an extreme situation? What restrictions would these changes impose on your daily work? How much effort/damage/resources would these changes cost? Is it easier to anticipate maintenance or to trust to luck that it won’t be necessary?

Easy production

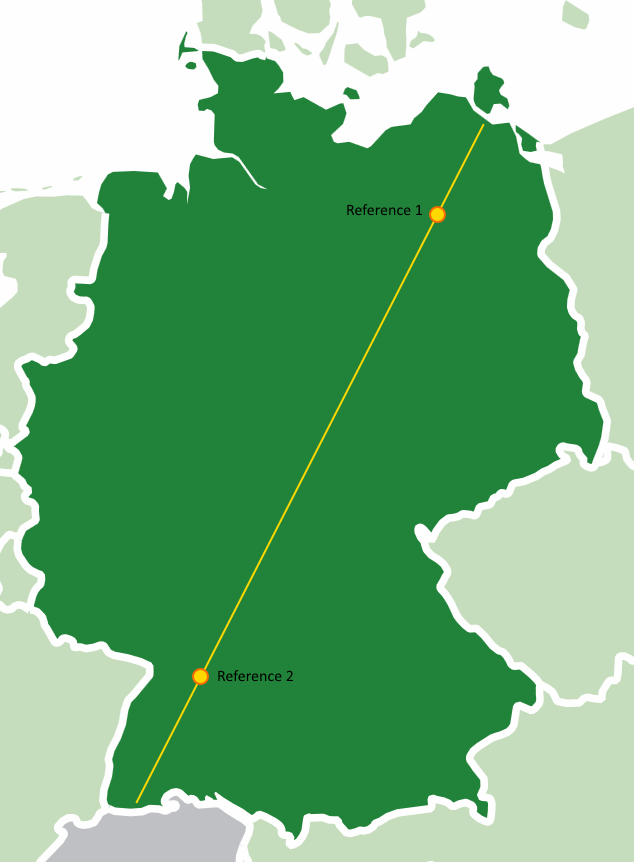
A while ago, I reviewed the code of a map tool. The user viewed a map and could click on it to mark a certain location. The geo coordinates of this location would be used as an input for further computations. The map was restricted to a fixed area, so the developer wrote the code in the easiest way possible: He chose well-known geographic landmarks on the map and determined their geo coordinates and pixel locations. map-with-referenceThose were the reference points in the code that every click would be related to. Using easy mathematic (rule of three), each point on the map could be calculated. Clever trick and totally working! The code practically wrote itself and the reference points only needed to be determined once.

Until the map was changed. The code contained some obscure constants that described the original landmarks, but the whole concept of arbitrary reference points was alien to the next developer. He was used to the classic concept of two reference points: top left and bottom right, with their respective geo coordinates and pixel locations. What seemed like a quick task turned into a stressful reclaiming of the clever trick during production.

In this example, the production (initial development) was easy, straight-forward and natural, but not easily reproducible during the maintenance phase (subsequent modification). The algorithm used a clever approach, but this cleverness isn’t necessarily available “under combat conditions”.

Go the extra mile

Most machines are designed so that wearing parts can be easily replaced. Think of batteries in electronic gagdets (well, at least before the gadget’s estimated lifetime was lower than the average battery life) or light bulbs in cars (well, at least before LED headlights were considered cool). Thing is, engineers usually know the wear effects their designs have to endure. There is no “usual wear effect” on software, due to lack of natural forces like gravitation. Everything could change, so it’s better to be prepared for all sorts of change. That’s the theory, but it’s not economically sound to develop software that is prepared for any circumstance. Pragmatic reasoning calls for compromise, like supporting changes that

  • are likely to happen (this needs to be grounded in domain knowledge and should be documented in the code)
  • are not expensive to arrange beforehands (the popular “low-hanging fruits”)
  • are expensive to implement afterwards

The last aspect might be a bit of a surprise, but it’s the exact aspect that came to play in the example above: To recreate the knowledge about the clever trick of landmark choices needed more time than implementing the classic interpolation taking the edge points.

So if you see a possible (and not totally unlikely) change that will be expensive to implement once the intimate knowledge of the code you have during the initial development, go the extra mile and prepare for it right now. Leave a comment, implement some kind of extension mechanism or just mind the code seams. In our example, slightly complicating the initial development led to a dramatically less clever and more accessible code.

Conclusion

You should consider writing your code for easy maintenance, even if that means additional effort during the initial implementation. Imagine that you yourself have to do the future change, stressed, over-worked and under time pressure, without any recollection about your thoughts today, lacking your familiar tools while your customer waits impatiently by your side. With proper preparation, even this scenario is feasible.


Recap of the Schneide Dev Brunch 2015-04-12

If you couldn’t attend the Schneide Dev Brunch at 12th of April 2015, here is a summary of the main topics.

brunch64-borderedA week ago, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. So if you bring a software-related topic along with your food, everyone has something to share. The brunch was a little sparsely attented this time but there was enough stuff to talk about. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Review of San Francisco

As it turned out, San Francisco might be half a planet away, but several of our attendees happened to live there for a while. They described the city and its culture to us and shared stories about specific persons and places. For a moment, San Francisco was just around the corner.

Review Ninja

One reason that San Francisco came up was the mentioning of Review Ninja, a second-generation code review tool with one of the coolest project URLs ever. If you ever were smitten by code review tools like gerrit, then Review Ninja might be worth a look. It has a lightweight and simplistic approach to a activity that could as well end up being a bureaucratic nightmare.

Be convincing

Another topic was the art of being convincing – to convince people of something useful but unfamiliar. We concluded that you cannot change people, no matter the effort. Only people can change people. You can try to facilitate their change, though. But don’t expect appreciation or even acknowledgement for your effort. Everybody will be convinced that they came up with the solution themselves. That’s the art of being convincing – or so we convinced ourselves.

Google recruitment process

We spent a lot of time discussing the Google recruitment process that one attendee had just successfully passed. But it’s a long and extensive process, so our timeframe fit. There is a book, “Cracking the Coding Interview” by Gayle Laakmann McDowell, that seems to be quite useful for preparation on the daylong in-depth interview marathon that needs to be mastered if you want to join Google. A number of similar books try to teach you the knowledge necessary to pass the recruitment process – not the job that usually follows, mind you, just the recruitment. Our participant counted more than thirty distinguishable contacts with Google during the process. The process itself is highly formalized, while interviews are performed by normal engineers on Google’s side. The comparability between applicants is achieved through the great number of interviews to even out random outliers.

Nearly all big IT companies utilize a similar recruitment process, so this insight can be applied nearly everywhere: If you want to be recognized as talented, you have to be prepared for the tests to come. Don’t assume that your interviewer presupposes anything about your abilities. Just because you have a degree in computer sciences doesn’t mean you know how to program, for example. They will test for that, and with rather challenging tasks, so better learn your stuff again.

Work environment

Anticipating the next topic, we talked about different workplace setups, like open-plan offices, separate rooms for everyone and the like. A great insight was that very different preferences exist. The ideal work environment of one developer is a nightmare for the next. And now imagine how difficult it gets to agree on a trade-off in a bigger team. We couldn’t even agree on music vs. silence for in-zone programming sessions, let alone the style of music that should be playing.

Room setup

As a practical exercise, we tried to rearrange the desks in the Softwareschneiderei to increase the number of desks on our second floor. We started without any restrictions on placement and iterated through several layouts, discussing several side-effects and drawbacks in our solutions. In the end, two applicable layout alternatives survived our weeding process. It was a lesson in group dynamics and emergent rulesets and even gave us a viable result.

 What defines object orientation?

We talked about the different approaches to define object orientation in terms of developer thinking. The classic approach of giving entities an identity was explored as well as the rather personal definition of flowing functionality instead of flowing data. We agreed that knowing all kinds of programming paradigms (with imperative, object oriented and functional being the major ones) enables developers to make the right choices for the task at hand. Being unable to choose leads to being ineffective fast.

The Java Memory Model

A short recap of the very informative and insightful talk about the Java Memory Model given by one of our attendees closed our brunch. The Java Memory Model (or any other memory model in fact) is a great help in determining if something weird can possibly happen with your code, like one thread observing a field X being set first and Y second, while another thread swears that Y was set first and X later. A memory model helps you to understand the quantum mechanics of your programming language and therefore survive multithreaded programming. And a simple rule will let you understand the vast majority of the Java Memory Model, as shown in the talk. I highly recommend you read up about the memory model of your favorite programming language.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.

Zoom out early, zoom out often

Often struck by yak shaving or target fixation? There’s a simple remedy: zoom out early, zoom out often.

Dennis Jarvis [CC BY-SA 3.0 (http://creativecommons.org/licenses/by-sa/3.0)], via Wikimedia Commons

A common pitfall of working long hours with high concentration level or stress level is the “yak shaving” effect. You start with a clear goal, dive down into the details and encounter an unforseen obstacle. No big problem, you just need to adjust focus for a moment and fix this little… but wait, in order to fix it, you first need to change this minor circumstance. And this change is prohibited by this effect, which needs to be adjusted, but relies on that. Much later, you’ll wake up from your dive and find yourself happily shaving a yak. But how exactly did you get there?

Avoid the yak

The best approach to counter yak shaving is “zooming out” of your current work in regular, externally triggered intervals and rehashing three aspects of your current work:

  • What do I want to achieve? (“Goal”)
  • What is my current task? (“Task”)
  • How does my task relate to my goal? (“Relationship”)

This “Goal/Task-Relationship” shouldn’t get too complicated. To describe your current Goal/Task-Relationship to a random person that just now arrived at the scene (ok, lets be clear: I’m talking about your boss), you should need at most two simple sentences. Every longer description is a sign of an unclear goal or inefficient steps (tasks) towards it.

To make sure that your Goal/Task-Relationship stays explainable, you could use the Pomodoro technique that partitions your concentrated work into intervals of half an hour (including the rehash phase).

Target fixation

The approach above helps against yaks, but not against target fixation. Target fixation occurs when you are so sure about your goal that you don’t question it even when the cost of achieving it rises to obscene levels. There are many stories I could tell about target fixation, but one sticks out for me because it happened myself and it happened recently.

The tragedy

In the midst of winter, during a cold period, my gas heater for the whole apartment broke down – on a late saturday evening. No amount of reading the manual, trying to turn it off and on again and maintainance routines could bring it back to life. The rooms grew colder. A long, cold weekend lay before me, but I couldn’t just sit it out – I had work to do with a tight deadline. So I frantically contacted one “24h emergency service” after the other with no success at all (this is in a rather big city, the experience really shocked me). My efforts to reach anybody who could help consumed time and nerves until I finally gave up. The backup option was to move to an hotel for two nights and I was ready to pack my things.

The remedy

oil-radiatorBut before I made the final decision to temporarily abandon the place, I called a friend to congratulate him on his birthday, totally unrelated to the heating desaster (it was on my todo list and needed to be done, so why not now?). After he asked me what’s up (he always senses misery) and I told him the whole catastrophe, he laughed and said: “Your problem can be solved with some money and a DIY store: just buy an oil radiator and plug it in – voilà, heating for one room”. I was baffled and excited: ten minutes later, and the store would be closed. In the last minute, I bought the radiator and had enough heat until the gas heater could be fixed during normal working days.

My target fixation is easily explained: “The gas heater broke down so I need to repair it/have it repaired”. The solution is also easy: “You need heating, but not necessarily by that broken gas heater”. It’s the same problem, just different zoom levels. By zooming out (being zoomed out, having somebody else provide the external view) of the narrow problem space I could see the whole picture and solve the real problem, not my perceived one.

Bird’s eye view

To counter target fixation, you have to zoom out regularly. But you need to zoom out even more and ask a different set of questions:

  • What problem do I want to solve? (“Problem”)
  • Can I think of a related, more generalized problem? (“Root”)
  • Have both problems the same cause? (“Cause”)

The “Problem Root Cause” approach helps to find a more abstract formulation of the problem at hand. You basically ask if you really solve a problem or merely a symptom of an hidden cause. In my story, I wanted to solve the problem of the broken gas heater. The generalized problem was lack of heating, regardless of which device it may provide. The cause was identical: cold weather without proper heating. Now I own an oil radiator on reserve.

Zoom out often

You really need to zoom out of your current work, take a few steps back and broaden your view to be sure about your path to the best solution. So my advice is to “zoom out early, zoom out often” (adapted from “commit early, commit often”). If you can manage the bird’s eye view of your path to the goal yourself, you’ll less often fall prey to yak shaving and target fixation.

Recap of the Schneide Dev Brunch 2015-02-08

If you couldn’t attend the Schneide Dev Brunch at 08th of February 2015, here is a summary of the main topics.

brunch64-borderedYesterday, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was well-attended but there was enough space for everyone. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Thoughts on the new brunch mechanics

We changed our appointment-finding process for the dev brunch this year. It’s now fixed-date, an appreciated remedy for the long doodle sessions before. But the reminder mail on the brunch mailing list is appreciated nonetheless. I hope to not forget it.

Thoughts on secure software development

Sparked by a talk about secure software development at the Objektforum series in Stuttgart, hosted by andrena Objects, we discussed typical weak points of development environments. Habits like “not my concern” or “somebody surely has approved of this” lead to situations when intruders (malicious or not) gain access to sensitive resources. Secure development begins with a security audit of the development area itself. We also want to note that just hanging out at the cafeteria of big IT companies and listening often gains crucial information that can be used in social engineering scenarios. We call the counter-measure “context awareness”. And for the Softwareschneiderei itself, being situated right next to a funeral parlor often calls for “social context awareness” (aka no laughter, no loud jokes) on our way to lunch.

Internal developer days

Two participating companies regularly hold internal “developer days” when the developers can do whatever they like, as long as its connected to software development. Both companies experience very positive results from it. We want to expand the Dev Brunch to something called the “Dev Event”, where we moderate workshops for developers. To start with it, we plan to perform the “Mäxchen” game event in March. Details and a doodle for the date finding (yes, we try to maximize participants here) will follow on the brunch mailing list.

IT security strategies

Based on the earlier discussion about secure software development, we talked about different security strategies for IT products and IT environments. The “walled castle” doctrine was highlighted. We touched topics like the recent BMW hack, the Heartbleed debacle and ready-to-use “secure” home cloud servers. Another discussion point was the TOR router that actually weakens the TOR effect. An example of top-notch obfuscation in sourcecode was a little piece of code that was thorougly examined, but still contained a surprising side effect (citation needed).

Experiences with Docker

The Docker virtualization tool is steadily climbing the hype cycle. So it’s only natural that we talk about it and share some tricks and insights. One topic was the use of Docker for High Performance Computing and a comparison of performance loss. The rule of thumb result was that Docker is “nearly native speed” (95%) while full virtual machines range in the 70% area. If you put different container tools under stress, they break in different ways. Docker will show increased latency, others lag in terms of CPU cycles, etc. The first rule of High Performance Computing is: there will be a bottleneck and it won’t be where you expect it to be.

Another tool mentioned is Docker Fig (a rather unlucky name for german ears). It’s the sugar coating needed to be productive with Docker, just like Vagrant for Virtualbox.

Tools for managing and orchestrating Docker containers are still in their childhood. We can’t wait for second-generation tools to emerge.

One magic ingredience to get the most out of virtualization is a SSD drive on the host. The cloud hosting provider DigitalOcean has a nifty offer where you can setup a virtual machine in one minute and pay a few cents for an hour of use. We truly live in exciting times.

New doctrines

We also talked about changes in the way computers are viewed and treated. The “pet vs. cattle” metaphor was an interesting take on the hardware admin’s realm. The “precious snowflake” syndrome is a sure sign of (too) old habits. For software applications to become “containerizable”, the “Twelve-Factor App” rules are the way to think and act. Plenty food for thought!

New gadgets

The Softwareschneiderei is the first company in germany to get hold of a Myo armband. This wireless gesture controller is worn like an oversized fitness tracker bracelet and combines a gyroscope with electromyographic data (the electric current in your arm muscles). This makes for an intuitive pointing device and an not-as-intuitive-yet finger/hand gesture detector. We each played a round of our custom game “Myo Huhn” (think Moorhuhn programmed over the weekend) and reached impressive scores on the first try. Sadly, the Myo isn’t ready for serious applications yet. Let’s see what future versions of this cool little device will bring. The example usages of their official video aren’t viable at the moment.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.

How we distribute our backups geographically

If you fear not only about single point of failure but even area of failure in your data security assessments, here is a simple and effective process to distribute your backups.

We are a software development company, so all of our most valueable assets are constantly endangered by hardware failure. We regularly do risk assessments in regard to data security and over the years created a fine-tuned system of duplication and doubled duplication to prevent data loss. Those assessments aren’t really complicated, you basically sit down, relax and think about your deepest fears on a certain topic. Then you write them down and act on their avoidance or circumvention. Here’s an example of some results:

  • No data transfer over unsecured internet connections
  • No single point of failure
  • No single area of failure

The last result is of particular interest today: We want to prevent data loss in case of “area-based desaster”, like a whole-building fire or meteorite impact. Well, to be clear on the meteorite scenario, it is both highly improbable and dangerous. If the meteorite happens to be just a bit bigger than average, we won’t worry about backups anymore because we all live in a perimeter around our company. Yes, worst-case scenarios are always morbid.

Stages of data-loss prevention

We have several measures in effect to prevent data-loss in place. Technologies like RAID drives and processes like daily backups and several copies of that backups make sure that we always have at least one copy of all important data even in the most drastic locally confined desaster. But to adhere to the first rule that no data transfer can happen over unsecured internet connections and to make sure that an internet connection isn’t a single point of failure that may compromise data security, we had to come up with a way to distribute our backups in a physical manner without much effort.

The backup export disks

Our system relies on three facts:

  • Small and resilient hard drives with high capacity are affordable
  • Every home of our employees can be an unique backup storage location
  • If we take turns, the effort is low for everybody, but high enough to be effective

So we bought an “backup export disk” for every employee. It’s an 2,5″ USB-powered hard drive with enough storage capacity to keep our most important data. All export disks are registered at the backup distribution system that can, upon connect, provide them with the most current backup. And a little “backup export token” that gets passed from employee to employee in a predetermined order. The token is just a piece of cardboard that says “tag, you are it!”.

Our backup export process

So what do you have to do when you find the “backup export token” on your desk? Just five easy steps:

  • Bring your backup export disk next day (this is the hardest part: remembering to bag the disk at home)
  • Plug it into the backup distribution system (a specific computer in off-state with an USB-cable) and switch it on
  • Wait for the system to do its job. This will take a while, but you’ll get an e-mail at completion, so just wait for the e-mail to arrive
  • Unplug the backup export disk and take it back home (store it in a dry and safe place)
  • Forward the backup export token to the next employee in line

That’s all there is to the obvious process. Some more things happen behind the scenes, but the process mostly relies on the effect of repetition by several operators.

Simple and effective

This process ensures that our backup gets “exported” at least thrice a week to different locations. All in all, we store our backup in at least five locations with a maximum age of two weeks. The system can scale up (or down) without limitation, so it won’t change even if we double or triple the location count or the export frequency. And any individual disk cannot be compromised as the data is secured by strong encryption, so there is no need to restrict physical access to it on the storage locations (like using a safe) or fret if a disk would get lost.

Decentralized, but supervised

Every time a backup export disk is connected to the backup distribution system, the disk’s health figures and remaining space is reported to the administrators. Using this information, we can also reconstruct the distribution history and fetch the most current disk in an emergency case. If a disk shows its age, it gets replaced by a new one without effort. We only need to tell the backup distribution system about it and associate it with an employee so that the e-mail is sent to the right person.

Conclusion

By assigning our employees with the core mechanics of keeping the backups distributed and automating the rest, we reached a level of data security that even protects against area effect scenarios.

The work experience improvement budget (“Kreativbudget”)

We gave our employees money to improve their work experience and it paid off tremendously. This blog entry describes the idea and rules behind it.

We at the Softwareschneiderei are a small team of software developers working in a founder-owned company. We develop software since 15 years now and have experimented with a lot of management ideas and concepts. We can conclude that a lot of things don’t work for us while others are highly effective. There is no guarantee that anything we do works anywhere else, so don’t expect wonders just because it works wonders for us. But we are willing to share nearly every detail of our management style, and here is another bit of it: the “creativity budget”.

I’ve already blogged about this idea five years ago, but it’s still a good (and fairly uncommon) idea, so why not do it again? The name “creativity budget” (“Kreativbudget” in german) is actually really bad, but it stuck and we cannot realistically change it anymore. A more fitting name would be “work experience improvement budget” or something similar. The core of the idea is simple: Every employee can spend a certain amount of money every year to improve his/her own work experience. The investment doesn’t need to be profitable, the improvement doesn’t need to be effective, whatever was bought, the employee never needs to justify it. It’s just company money that the employee can rule over to improve the company in his/her fashion.

The actual ruleset is fairly simple: In recent years, the amount was defined to be 1000 EUR per year for each employee, regardless of actual job (development or administration, for example). Our students could invest half the amount (500 EUR). You don’t need to buy coffee or food, your work computer or laptop, all the basics are provided outside of the budget. You shouldn’t spend the budget on silly things just to get rid of it, but if you have an idea – even a crazy one – and think, “hey, that would be cool to have”, you just need to create a “purchase order” issue in our administration issue tracker and flag it as “on creativity budget”. We will buy it right away, without further discussion.

Why the creativity budget?

The most competent person to improve the work experience of an employee is he himself. Every hurdle we impose between him and his improvement ideas, like bureaucratic overhead or reviews, will only damage the improvement effect, but not improve the financial situation of the company. Our financial situation is directly linked to the productivity and happiness of all employees, so we will actually damage it by trying to go cheap. Not spending money won’t buy us happiness. And remember, we are a small company. The maximum amount of all creativity budgets combined is still only a small percentage of our total revenue (under 2%). If we can improve our total revenue just a little bit, it is totally worth it. But why speculate? We have hard numbers from the last dozen years that show that it works for us.

What did the budget gain us?

The most important gain is making room for errors. If you have to plea and convince higher-ups of an improvement, it better has convincing figures and a realistic chance of success. If not, you are the moron that suggested it. Using our budget, we can try crazy things and never need to explain ourselves. If it doesn’t work – who cares? If it works – well, you were the first, now we need to implement it for everyone.
We try things earlier. New technologies like solid state disks were frowned upon in the beginning – how long do they last, etc. We tried them early and got convinced quicker than most (but that’s another blog post).
We don’t calculate improvements first. One of the most common refusals for a new idea is the worry “what if everybody wants one?”. That’s the fear of upscaling paired with the fear of failure. What if the idea works and is a huge improvement and nobody wants it? We rather err on the side of monetary losses instead of productivity loss.

But what did it gain us precisely?

Well, to answer that, I have to present you the three categories of improvements we identified (without limiting the budget to them!):

  • Hardware: A certain piece of technology believed to make work easier or more enjoyable. Examples are computer mouses (everyone has his favorite mouse), keyboards, monitor upgrades (if the default double 24″ aren’t enough), SSDs (before we got rid of spindle disks) or even your favorite computer brand. It gained us fine-tuned workplaces that fit perfectly with the developers using them – no “one size fits all”.
  • Software: A computer program that you’d like to use even if that requires license costs. Examples are IDEs, editors, version control clients or even screenshot utilities. Don’t get me wrong – we had all these things before, but mostly open source products. If you want a commercial twin of a software, you don’t have to argue. It made our software landscape more diverse and introduced some products for the whole company – SmartGit is the example of choice.
  • Wetware: An activity you’d like to undertake – in the professional context of your job. You want to visit that certain conference? Have paid training on a specific topic? This category introduced us to some conferences that are worth revisiting and some we’ve already forgotten again. We got trainings and went to workshops, without any upfront filtering or “strategic planning”.

We’ve gained a lot of agility in pursuing technical excellence, each of us on his/her own course. We gained the insight that “work experience” is something we can directly influence and steer. It makes already self-confident employees even more confident. And it relieves the boss from important, but highly individual micro-management (but that’s just my own personal gain from it all).

Summary

In giving every employee the power to improve his/her direct work experience, we improved our overall experience even more. In all these years, we never used up the budgets completely, but the effect is very noticeable. We acted on impulse, tried it out, reflected and adopted it if worthwhile. And it was very worthwhile indeed. Currently, we discuss the idea to double or even triple the budget per year and see where it leads us.

Recap of the Schneide Dev Brunch 2014-12-14

If you couldn’t attend the Schneide Dev Brunch at 14nd of December 2014, here is a summary of the main topics.

brunch64-borderedIn mid-december, we held another Schneide Dev Brunch, a regular brunch on a sunday, only that all attendees want to talk about software development and various other topics. If you bring a software-related topic along with your food, everyone has something to share. The brunch was well-attended and we didn’t even think about using the roof garden (cold and rainy). There were lots of topics and chatter. As always, this recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

International brunch

We tried to establish a video conference with a guest from San Francisco and had tried the technical implementation beforehands. But we didn’t succeed, mostly because of a sudden christmas party on the USA side. So we can’t really say if the brunch character is preserved even if you join us in the middle of the (local) night.

How much inheritance do you use?

One question was how inheritance is used in the initial development of systems. Is it a pre-planned design feature or something that helps to resolve difficult programming situations in an ad-hoc manner? How deep are the inheritance levels?
The main response was that inheritance is seldom used upfront. The initial implementations are mostly free of class hierarchies. Inheritance is often used after the fact to extract abstractions (or generalizations) from the code. The hierarchies mostly grow “upwards” from the concrete level to abstract superclasses.
Another use case of inheritance is the handling of special cases with further specialization through subclasses. The initial class is modified just enough to enable proper insertion of the new code in its own subclass.
A third use case of inheritance, upfront this time, was proposed in regard of the domain model. Behavioural typing is a common motivation for the usage of inheritance in the model, as contrasted to the technical usage of inheritance to solve non-domain problems. In the domain level, inheritance resembling a “behaves-like” relation can be the most powerful expression of actual connections between types.

Book review “Analysis patterns”

The discussion about inheritance led to questions about domain models and their expression through formal notation. An example about accounts resulted in a short review of the book “Analysis Patterns”, written by Martin Fowler in 1999. The book introduces its own notation for models to be able to express the interrelations without being dragged down into the implementation level. UML isn’t suited as it’s a notation from the technical domain. Overall, the book seems to be mostly overlooked and under-appreciated. It contains a lot of valueable wisdom in the area of domain analysis, an activity that has to be done upfront of any larger project. This “upfront activity” characteristics might have led to it being ignored in most agile processes. The book is a perfect companion to Eric Evan’s “Domain-Driven Design”.

Book review “Agile!”

Another book review of this brunch was a deep review of Bertrand Meyer’s book “Agile! The Good, the Hype and the Ugly”. The book is the written opinion of Mr. Meyer in regard of all current agile processes and very polarizing as such – he does state his points clearly. But it’s also a very well-researched assessment of nearly all aspects of agile software development. You might want to argue with certain conclusions, but you’ll have to admit that Mr. Meyer knows what he’s talking about and got his facts right (even if his temper shines through sometimes). This book is the perfect companion to all the major agile books you’ve read. It serves as a counter-balance to the dogmatic views that sometimes come across. And it serves as a (albeit personal) rating of all agile practices, a gold mine for every project manager out there. the book itself is rather short with some reiterations (you’ll get the major points, even if you skip some pages) and written in an informal tone, so it’s an easy read as long as you’re neutral towards the topic.
When we reviewed the rating of agile practices on a big whiteboard, ranging from ugly to brilliant, it didn’t took long until discussions started. If nothing else, this book will help you review your practices and beliefs.

Embedded Agile on the rise

The next topic was related to agile software development, too. In the large field of embedded software development, adoption of agile practices lagged behind substantially. This has many reasons, of which we discussed a few, but the more interesting trend was that this changes. While there is still a considerable lack of literature for embedded software overall, the number of publications advocating modifications to the agile processes to fit the intricacies of embedded software development is steadily increasing.
A similar trend can be observed in the user experience community (think: user interface designers), termed “lean UX“.

Mobile game presentation

A long-awaited highlight of this brunch was the presentation of a mobile platforms game under development by one attendee. It’s a cool-looking Jump-and-Run game in the tradition of Super Mario, with lots of gimmicks and innovative effects. The best part of the presentation was the gameplay, controlled by the developer from behind the device, upside down and with live commentary. The game is developed in a platform-agnostic manner using several frameworks and suitable coding habits. Right now, it’s in its final phase of development and will be released soon. I don’t want to spoil too much beforehands and invite Martin (the author) to insert a comment below with links leading to more information.

A change in the Dev Brunch mechanics

The last topic on our agenda was a short review of the Dev Brunch series in the last years. In 2013, we introduced the extra “workshop events” that were adapted to the “game nights” in 2014. We want to return to more serious topics in 2015 and revive the workshops. Attendees (and future ones) are invited to make suggestions which workshop they would like to see. The Dev Brunch itself will be formalized further by introducing a steady pace of bi-monthly dates.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.