Every time you write a getter, a function dies

This blog post explores the difference between classic and Tell, don’t Ask-style code without any sourcecode examples.

Don’t be too alarmed by the title. Functions are immortal concepts and there’s nothing wrong with a getter method. Except when you write code under the rules of the Object Calisthenics (rule number 9 directly forbids getter and setter methods). Or when you try to adhere to the ideal of encapsulation, a cornerstone of object-oriented programming. Or when your code would really benefit from some other design choices. So, most of the time, basically. Nobody dies if you write a getter method, but you should make a concious decision for it, not just write it out of old habit.

One thing the Object Calisthenics can teach you is the immediate effect of different design choices. The rules are strict enough to place a lot of burden on your programming, so you’ll feel the pain of every trade-off. In most of your day-to-day programming, you also make the decisions, but don’t feel the consequences right away, so you get used to certain patterns (habits) that work well for the moment and might or might not work in the long run. You should have an alternative right at hands for every pattern you use. Otherwise, it’s not a pattern, it’s a trap.

Some alternatives

Here is an incomplete list of common alternatives to common patterns or structures that you might already be aware of:

  • if-else statement (explicit conditional): You can replace most explicit conditionals with implicit ones. In object-oriented programming, calling polymorphic methods is a common alternative. Instead of writing if and else, you call a method that is overwritten in two different fashions. A polymorphic method call can be seen as an implicit switch-case over the object type.
  • else statement: In the Object Calisthenics, rule 2 directly forbids the usage of else. A common alternative is an early return in the then-block. This might require you to extract the if-statement to its own method, but that’s probably a good idea anyway.
  • for-loop: One of the basic building blocks of every higher-level programming language are loops. These explicit iterations are so common that most programmers forget their implicit counterpart. Yeah, I’m talking about recursion here. You can replace every explicit loop by an implicit loop using recursion and vice versa. Your only limit is the size of your stack – if you are bound to one. Recursion is an early brain-teaser in every computer science curriculum, but not part of the average programmer’s toolbox. I’m not sure if that’s a bad thing, but its an alternative nonetheless.
  • setter method: The first and foremost alternative to a state-altering operation are immutable objects. You can’t alter the state of an immutable, so you have to create a series of edited copies. Syntactic sugar like fluent interfaces fit perfectly in this scenario. You can probably imagine that you’ll need to change the whole code dealing with the immutables, but you’ll be surprised how simple things can be once you let go of mutable state, bad conscience about “wasteful” heap usage and any premature thought about “performance”.

Keep in mind that most alternatives aren’t really “better”, they are just different. There is no silver bullet, every approach has its own advantages and drawbacks, both shortterm and in the long run. Your job as a competent programmer is to choose the right approach for each situation. You should make a deliberate choice and probably document your rationale somewhere (a project-related blog, wiki or issue tracker comes to mind). To be able to make that choice, you need to know about the pros and cons of as much alternatives as you can handle. The two lamest rationales are “I’ve always done it this way” and “I don’t know any other way”.

An alternative for get

In this blog post, you’ll learn one possible alternative to getter methods. It might not be the best or even fitting for your specific task, but it’s worth evaluating. The underlying principle is called “Tell, don’t Ask”. You convert the getter (aka asking the object about some value) to a method that applies a function on the value (aka telling the object to work with the value). But what does “applying” mean and what’s a function?
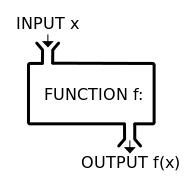
191px-Function_machine2.svgA function is defined as a conversion of some input into some output, preferably without any side-effects. We might also call it a mapping, because we map every possible input to a certain output. In programming, every method that takes a parameter (or several of them) and returns something (isn’t void) can be viewed as a function as long as the internal state of the method’s object isn’t modified. So you’ve probably programmed a lot of functions already, most of the time without realizing it.

In Java 8 or other modern object-oriented programming languages, the notion of functions are important parts of the toolbox. But you can work with functions in Java since the earliest days, just not as convenient. Let’s talk about an example. I won’t use any code you can look at, so you’ll have to use your imagination for this. So you have a collection of student objects (imagine a group of students standing around). We want to print a list of all these students onto the console. Each student object can say its name and matriculation number if asked by plain old getters. Damn! Somebody already made the design choice for us that these are our duties:

  • Iterate over all student objects in our collection. (If you don’t want to use a loop for this you know an alternative!)
  • Ask each student object about its name and matriculation number.
  • Carry the data over to the console object and tell the console to print both informations.

But because this is only in our imagination, we can go back in imagined time and eliminate the imagined choice for getters. We want to write our student objects without getters, so let’s get rid of them! Instead, each student object knows about their name and matriculation number, but cannot be asked directly. But you can tell the student object to supply these informations to the only (or a specific) method of an object that you give to it. Read the previous sentence again (if you’ve not already done it). That’s the whole trick. Our “function” is an object with only one method that happens to have exactly the parameters that can be provided by the student object. This method might return a formatted string that we can take to the console object or it might use the console itself (this would result in no return value and a side effect, but why not?).  We create this function object and tell each student object to use it. We don’t ask the student object for data, we tell it to do work (Tell, don’t Ask).

In this example, the result is the same. But our first approach centers the action around our “main” algorithm by gathering all the data and then acting on it. We don’t feel pain using this approach, but we were forced to use it by the absence of a function-accepting method and the presence of getters on the student objects. Our second approach prepares the action by creating the function object and then delegates the work to the objects holding the data. We were able to use it because of the presence of a function-accepting method on the student objects. The absence of getters in the second approach is a by-product, they simply aren’t necessary anymore. Why write getters that nobody uses?

We can observe the following characteristics: In a “traditional”, imperative style with getters, the data flows (gets asked) and the functionality stays in place. In a Tell, don’t Ask style with functions, the data tends to stay in place while the functionality gets passed around (“flows”).

Weighing the options

This is just one other alternative to the common “imperative getter” style. As stated, it isn’t “better”, just maybe better suited for a particular situation. In my opinion, the “functional operation” style is not straight-forward and doesn’t pay off immediately, but can be very rewarding in the long run. It opens the door to a whole paradigm of writing sourcecode that can reveal inherent or underlying concepts in your solution domain a lot clearer than the imperative style. By eliminating the getter methods, you force this paradigm on your readers and fellow developers. But maybe you don’t really need to get rid of the getters, just reduce their usage to the hard cases.

So the title of this blog post is a bit misleading. Every time you write a getter, you’ve probably considered all alternatives and made the informed decision that a getter method is the best way forward. Every time you want to change that decision afterwards, you can add the function-accepting method right alongside the getters. No need to be pure or exclusive, just use the best of two worlds. Just don’t let the functions die (or never be born) because you “didn’t know about them” or found the style “unfamiliar”. Those are mere temporary problems. And one of them is solved right now. Happy coding!

Recap of the Schneide Dev Brunch 2016-04-10

If you couldn’t attend the Schneide Dev Brunch at 10th of April 2016, here is a summary of the main topics.

brunch64-borderedLast sunday, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. In case you miss the recap article about the february brunch: It didn’t happen. We all took a break, but are on track again. So if you bring a software-related topic along with your food, everyone has something to share. We were quite a lot of developers this time, so we had enough stuff to talk about. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:
Why software development conferences?

We began with a curious question: Why are there even conferences about software development? You can read most of the content for free on the internet and even watch the talks afterwards. So why attend one for a lot of money? We discussed the topic a bit and came up with an analysis:
There are (at least) four different interested groups in a conference:

  • The organizer or commercial host is mostly interested in a positive revenue. As long as there’s a possibility for some net gain, somebody will host a conference. The actual topic is a secondary matter for them (this might explain some of the weirder conferences out there, like the boring conference).
  • The developers that really attend a conference are a small subset of all developers. They all have their own personal motives to pay money and invest time and inconviences to be there in person. Some might rely on the quality filter of a conference board, some are looking forward to meet their peers in an annual ritual. There might be those that can learn best if somebody talk-feeds them the topic. Whatever reason, a lot of developers enjoy participating at conferences. If it happens to be paid by the employer and booked as worktime, who would not?
  • Then there are the speakers. They have the additional burden to convince a committee of their topic, prepare a talk of high quality and be able to perform on stage (something that is harder than it looks). The speakers seek reputation and credible proof of expertise. His resume will probably profit, too.
  • And at last, the companies that sponsor the conference, maintain a booth with big roll-ups and smiling employees and give their developers a chance to attend are in the game to represent, to recruit and build their brand. A lot of traditional marketing effort goes into trade fairs, so why not treat the developer market like any other and be present in the developer fairs?

We can conclude that software development conferences can provide value for every associated stakeholder. As long as this sentence holds true, conferences will be held.
The question didn’t came out of the blue: one of our attendees got accepted as a speaker on the Karlsruher Entwicklertag 2016 and wanted to learn about the different expectations he needs to address. He will give his talk on the next Dev Brunch to practice the flow and to pass the hardest critics. The topic: git internals. We are thrilled!

Stratagems and strategies

The next topic contained another talk, not at a conference, but in the context of a “general topics” series at a local university (the Duale Hochschule in Karlsruhe). The talk introduces the concept of the 36 stratagems and of modern strategies to the audience. We talked a bit about the concept itself and found that the list of logical fallacies is somewhat similar. We even found an application of the stratagems in local history (sorry, only german source found): The Bretten’s Hundle
The talk itself is this monday, so you’ll need to hurry if you want to attend.

Psychology of deception

As often during the dev brunch, one topic led to the other, and we soon talked about morale and ethics. The concept of micro-expressions to reveal the hidden agenda of others came up, as well as the TV series “lie to me” that is inspired by the work of Paul Ekman, a professor of psychology. There even is a commercial training program to improve your skill of “spotting the liar”.

Games with morale aspects

Well, we are nerds. While crime investigation is thrilling, there is the even more enthralling topic of games with psychological and moralistic aspects. We soon exchanged our experiences with games like “Haze” or “Spec Ops: The Line”. But it doesn’t stop at shooter games, you can have similar insights by playing “Papers, Please” (a strong favorite for one of our next Schneide game nights) or “This War Of Mine”. You can even try some multiplayer games specifically designed for social insights, like “The Ship: Murder Party”.
And if you haven’t got much time but still want to learn something about yourself, little games like “60 Seconds!” are a great start.
This topic lead to some ideas for upcoming Schneide game nights in 2016.

Book review: A tour of C++

One attendee of the brunch provided a summary of the book “A Tour of C++” from Bjarne Stroustrup, that recently got updated to the language possibilities of C++ 11. In his words, the book is a rather incomplete introduction to the language, with way too many aspects described in a way too short manner. It’s more of a reading list to really grasp the concepts, so it may serve as a source of inspiration. For example, the notion of “move semantics” was explained, but to discover the consequences is up to the developer. The part about template programming was well done and every chapter has a suitable list of advices in the tradition of “Effective XYZ” at the end. So it’s not a bad book, but too short to be satisfying. It’s like a tourist’s tour around C++ 11, so the title holds its promise.

The left-pad incident

When we finished the “official” agenda, the topic of the recent left-pad incident came up and left us laughing. We really live in glorious times when the happiness of the (Javascript) world depends on a few lines of code. Not that this couldn’t happen in any other ecosystem.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.

Timestamps make horrible identifiers

If you think about using a timestamp or date as an identifier for some kind of entity, object or data record – think again. They are horribly ill-equipped to be identifiers due to their dynamic resolution. Here’s the story how we got to this conclusion.

vetre / fotoliaNot long ago, I’ve struggled with a system that uses timestamps as entity identifiers. What can I say? Timestamps aren’t meant to identify anything else than a specific point in time. Don’t use them as entity identifiers, ever. If you want to know why, I invite you to read on. The blog post is written in Freytag’s dramatic structure for added effect.

Exposition

We’ve designed a system that runs on multiple instances that communicate in all sorts of way. A central archive instance stores all data related to measurements. The whole network revolves around the notion of measurement. Measurement data is the most precious data and all instances will either produce or consume data based on these measurements.

Most important for human operators is an instance that lets you view all existing measurement data. Let’s call it the viewer. The viewer displays an overview list of all measurements in a given context and lets the operator choose to view ever more details of any of them. To be able to provide the overview list as fast as possible, we added a cache that holds the information.

Rising action

This measurement list cache was the source of all kinds of peculiar behaviour of the system. Most, but not all measurement data was incomplete. The list cache entries were assembled from different sources that were available at different times, so it seemed that while one part of the data got written to the cache, another part couldn’t be written for whatever reasons. The operator could load detailed data of some few measurements, but the majority just produced an error message that the data couldn’t be found (despite it being present).
The most obviously broken functionality left the following trace in the log files (paraphrased):

- storing measurement at 2016-02-28T13:25:55.189+01:00 into the list cache
- measurement stored
[...]
- loading measurement at 2016-02-28T13:25:55.189+01:00 from the list cache
- error: measurement not found in list cache

So, the system is essentially telling me that it can’t load some data it just stored. As you can imagine, this may lead to some questions about the sanity of the database product underneath.

Climax

After some investigation and fruitless integration testing, it dawned me: The problem wasn’t timing or the database. All the bugs could be explained with only one circumstance: Measurements were ultimately identified by their timestamp, the moment the measurement was made. There’s also a location, type and some other information in the identifier for each measurement, but only the timestamp changes between two measurements in the same narrow context. And the timestamp was stored in different precisions, depending on the origin of the measurement identifier. Most identifiers were create at the measurement producing system instances (let’s call them measurers) and had millisecond precision. As soon as they got stored in the production database (but not our development database), they lost the milliseconds. And some of the most important measurement data got exported to third-party systems, using a minute-based precision. So we had one measurement identifier in the system, but with three different types, each mostly incompatible to each other.

Falling action

That’s why the log excerpt above never occurred in development, but in production: The measurement is stored in the database, the used identifier gets passed around in the software, but a query on the exact same identifier in the database yields no result because the timestamps now differ in the millisecond range. And the strange effects that sometimes, everything worked just fine? That’s when the milliseconds are zero by chance. Given that most actions in the system are scheduled and performed automatically exactly on the zero mark, the zero milliseconds case happened more often than it would in an even distribution.

Our system dealt with three types of measurement identifiers: Millisecond-precise identifiers produced by the measurers, second-precise identifiers used by the measurement list cache and minute-precise identifiers used (and sometimes fed back into the system) by the data export. These identifiers were incompatible even for the same measurement most of the time, but not always. In unit tests, the timestamps were made up and didn’t reveal the problem properly (who thinks about odd milliseconds when making up a timestamp?).

My solution was to pull this incompatibility up into the type system. Instead of one measurement identifier, there are now three measurement identifiers: MillisecondPreciseIdentifier, SecondPreciseIdentifier and MinutePreciseIdentifier. An identifier of higher precision can be converted to an identifier of lower precision, but not the other way around. Everytime a measurement identifier is created, it needs to explicitely state its precision of the timestamp. This made the compiler highlight the problematic usages clearly as type conflicts and therefore dealing with the problem much easier.

Revelation

Choosing a timestamp as a vital part of a (measurement) identifier was a mistake from the beginning. The greater problem was the omission of the timestamp’s precision. Timestamps perform more like floating-point numbers and less like integers, even if every timestamp can be represented by a long. As soon as I made the precision of each timestamp clear to the compiler, the bugs revealed themselves. The annoying difference between developer and production database would have been detected much sooner, because a millisecond-precise timestamp will now warn in the log files if its millisecond part is zero. As soon as this log entry is seen very often, its clear that something is wrong. The new datatypes not only serve as a clearer API contract definition tool, but also as a runtime sanity check.

If you don’t want to repeat this mistake, keep in mind that each timestamp, date or whatever time-related data type you use will inherently have a maximum precision. As soon as you mix different precisions into the same data type, you’re going to have a bad time. Explicitely state the required precision in your type system and your compiler will keep an eye on it, too.

Our five types of configuration

Over the years, we came up with a strategy to handle configurable aspects of our software applications. Using five different types of configuration, we are able to provide high customizability with modest effort.

settings © vege / fotoliaConfigurable aspects of software are the magical parts with which you can achieve higher customer satisfaction with relatively modest investment if done right. Your application would be perfect if only this particular factor were of the value three instead of two as it is now. No problem – a little tweak in the configuration files and everything is right. No additional development cost, no compile/build cycle. You can add or increase business value with a simple text editor when things are configurable.

The first problem of this approach is the developer’s decision what to make configurable. Every configurable and therefor variable value of a software system requires some sort of indirection and additional infrastructure. It suddenly counts as user input and needs to be validated and sanitized. If your application environment requires an identifier like a key, the developer needs to come up with a good one, consistent to the existing keys and meaningful enough to make sense to an unsuspecting user. In short, making something configurable is additional and hard work that every developer tries to avoid in the face of tight deadlines and long feature lists.

Over-configurability

Our first approach to configurable content of our applications lead to a situation where everything could be configured, even the name and location of the configuration files themselves. You had to jump through so many hoops to get from the code to the actual value that it was a nightmare to maintain. And it provided virtually no business value at all. No customer ever changed the location of only one configuration file. All they did was to change values inside the configuration files once in a while. Usually, the values were adjusted once at first installation and once some time later, when the improvement of the change could be anticipated. The possibility of the second adjustment usually brings the customer satisfaction.

Under-configurability

So we tried to narrow down the path of configurable aspects by asking our customers for constant values. We are fortunate to have direct customer access and to develop a lot of software based on physics and chemistry, science fields with a high rate of constants. But the attempt to embed natural constants directly in the code failed, too. Soon after we installed the first software of this kind, an important constant related to neutron backscattering was changed – just a bit, but enough to make a difference. Putting important domain values in the code just doesn’t cut it, even if they are labeled constants and haven’t changed for decades.

The five types

A good configurable software application finds the sweet spot between being completely configurable and totally rigid. To help you with this balancing, here are the five types of configuration we identified along our way:

Resources

The section containing the resources of the application isn’t meant to be introspected or edited by the user. It contains mostly binary data like images or media formats and static content like translations. Most resources are even bundled into archive files, so they don’t present themselves as files. All resources are overwritten with every new version of the application, so changing for example an icon is possible, but only has a short-term effect unless it is fed back into the code base. If the resources were deleted, the application would probably boot up, but lack all kind of icons, images and media. Most language content would be replaced by internationalization keys. In short, the application would be usable, but ugly.

(Manufacturer) Settings

We call every configurable option that is definitely predefined by the developer a setting. We group these options into a section called settings. Like resources, settings are overwritten with every new version of the application, so changes should be rare and need to be reported back into development. Settings are configurable if the urgent need arises, but are ultimately owned by the developers and not by the users. The most delicate decision for a developer is to distinguish between a setting and an option. Settings are owned by the developer, options are owned by the user. If the settings were deleted, the application would most likely not boot up or use hard-coded defaults that might not be suited for the given use case. We use settings mostly for feature toggles or dynamically loaded content like menu definitions or team credits.

Options

This is the most interesting type of configurable in terms of user centered business value. Every little bit of information in the option section is only deployed once. As soon as it can be edited by the user, it belongs to the user. We deliver nearly every property, config or ini file as an option. We fill them with nondestructive defaults and adjust the values during the initial deployment, but after that, the user is free to change the files as he likes. This has three important implications for the developer:

  • You can’t rely on the presence of any option entry. Each option entry needs to have a hardcoded fallback value that takes over if the entry is missing in the files.
  • Every new option entry needs to be optional (no pun intended). Since we can’t redeploy the option files, any new entry won’t exist in an existing installation and we can’t force the user to add it. If you can’t find a sensible way to make your option optional, you’re going to have a hard time.
  • If you need to make changes to existing option files, you need to automate it because the number of installations might be huge. We’ve developed our own small domain specific language for update scripts that perform these changes while maintaining readability. Update scripts are the most fragile part of an update deployment and should be avoided whenever possible.

The options are what makes each installation unique, so we take every measure to avoid data loss. All options are in one specific directory tree and can be backuped by a simple copy and paste. Our deliverables don’t contain option files, so they can’t be overwritten by manual copy or extract actions. If the options were deleted, the application would boot up and recreate the initial options with our default values, therefor losing its uniqueness.

(Mutable) Data

The data section is filled with mutable information that gets created by the application itself. It’s more of a database implemented in files than real configuration. The user isn’t encouraged to even look into this section, let alone required to edit anything by hand. If this section would be deleted, the application would lose parts of its current state like lists of pending tasks, but not the carefully adjusted configurables. The application would boot up into a pristine state, but with a suitable configuration.

Archive

The last type isn’t really a configuration, but a place for the application to store the documents it produces as part of its user-related functionality. Only the application writes to the archive, and only in a one-time fashion. Existing content is never altered and rarely deleted. The archive is the place to look for results like measurement data or analysis reports. It’s very important to keep the archive free of any kind of mutable data. If the archive would be deleted, all previously produced result documents would be lost, but the application would work just fine.

Summary

As you’ve seen, we differentiate between five types of configurables, but only two types are “real” configuration: The settings belong to the developer while the options belong to the user. We’ve built over a dozen successful applications using this strategy and are praised for their configurability while our required effort for maintainance is rather low.

Let us know if you have a similar or totally different concept for configurables by dropping a comment.

The whole company under version control

One of our secrets is that we’ve put the whole company under version control. You can see every change to our business data and undo every mistake.

by Sashkin / fotolia

A minor fact about the Softwareschneiderei that always evokes surprised reactions is that everything we do is under version control. This should be no surprise for our software development work, as version control is a best practice for about twenty years now. If you aren’t a software developer or unfamiliar with the concept of version control for whatever reasons, here’s a short explanation of its main features:

Summary of version control

Version control systems are used to track the change history of a file or a bunch of files in a way that makes it possible to restore previous versions if needed. Each noteworthy change of a file (or a bunch of files) is stored as a commit, a new savepoint that can be restored. Each commit can be provided with a change note, a short comment that describes the changes made. This results in a timeline of noteworthy changes for each file. All the committed changes are immutable, so you get revision safety of your data for almost no cost.

Usual work style for developers

In software development, each source code file has to be “in a repository”, the repository being the central database for the version control system. The repository is accessible over the network and holds the commits for the project. One of the first lessons a developer has to learn is that source code that isn’t committed to a version control system just doesn’t exist. You have to commit early and you have to commit often. In modern development, commit cycles of a few minutes are usual and necessary. Each development step results in a commit.

What we’ve done is to adopt this work style for our whole company. Every document that we process is stored under version control. If we write you a quote or an invoice, it is stored in our company data repository. If we send you a letter, it was first committed to the repository. Every business analysis spreadsheet, all lists and inventories, everything is stored in a repository.

Examples of usage scenarios

Let me show you two examples:

We have a digital list of all the invoices we sent. It’s nothing but a spreadsheet with the most important data for each invoice. Every time we write an invoice, it is another digital document with all the necessary text and an additional line in the list of invoices. Both changes, the new invoice document and the extended list are included in one commit with a comment that hints to the invoice number and the project number. These changes are now included in the ever-growing timeline of our company data.

We also have a liquidity analysis spreadsheet that needs to be updated often. Every time somebody makes a change to the spreadsheet, it’s a new commit with a comment what was updated. If the update was wrong for whatever reason, we can always backtrack to the spreadsheet content right before that faulty commit and try again. We don’t only have the spreadsheet, but the whole history of how it was filled out, by whom and when.

Advantages of version controlled files

Before we switched to a version controlled work style, we had network shares as the place to store all company data. This is probably the de-facto standard of how important files are handled in many organizations. Adding version control has some advantages:

  • While working with network shares, everybody works on the same file. Most programs show a warning that another user has write access on a file and only opens in read-only mode. But not every program does that and that’s where edit collisions occur without anybody noticing. With version control, you work on a local copy of the file. You can always change the file, but you will get a “merge conflict” when another user has altered the file in the repository after your last synchronization. These merge conflicts are usually minor inconveniences with source code, but a major pain with binary file formats like spreadsheets. So you’ll know about edit collisions and you’ll try to avoid them. How do you avoid them? By planning and communicating your work better. Version control emphasizes the collaborative work setting we all live in.
  • Version controlled data is always traceable. You can pinpoint exactly who did what at which time and why (as stated in the commit comment). There is no doubt about any number in a spreadsheet or any file in your repository. This might sound like a surveillance nightmare, but it’s more of a protection against mishaps and honest errors.
  • Version control lets you review your edits. Every time you commit your work, you’ll see a list of files that you’ve changed. If there is a file that you didn’t know you’ve changed, the version control just saved your ass. You can undo the erroneous change with a simple click. If you’d worked with network shares, this change would have gone unnoticed. With version control, you have to double-check your work.
  • There are no accidental deletions with version control. Because you have every file stored in the repository, you can always undo every delete operation. With network shares, every file lives in the constant fear of the delete key. With version control, you catch your mishap in the commit step and just restore the file.

Summary of the adoption

When we switched to version control for every company data, we just committed our network shares in the repository and started. The work style is a bit inconvenient at first, because it is additional work and needs frequent breaks for the commits, but everybody got used to it very fast. Soon, the advantages began to outweight the inconvenience and now working with our company data is free of fear because we have the safety net of version control.

You want to know more about version control? Feel free to ask!

The tables will eventually turn for every optimization

Nearly all performance optimizations turn sour sooner or later. Here’s a story that illustrates the concept and gives a simple ruleset to avoid the effect.

An inconvenient truth

One of the things every software developer has to learn the hard way is that performance optimizations are a bad thing most of the time. The lesson is counter-intuitive because it is in conflict with several fundamental motivations of our artist/engineer attitude:

  • We want our code to be as fast as possible or even faster. (We really like the prospect of making the impossible happen!)
  • We don’t want to waste resources if it can be avoided. (Digital resources have always been scarce. Development in abundance wasn’t taught!)
  • We want to be clever and one-up everybody with the latest trick/hack. (This ego boost driven development attitude is a major problem on its own!)

But we can’t deny that clever guys exist since forever and that their wisdom should be considered. Here’s one clever guy fourty years ago:

premature optimization is the root of all evil.

said Donald Knuth in 1974. A typical computer had RAM in the lower kilobyte range these days and clocked with around a megahertz. The Intel 8080 was introduced in this year. No sign of abundance all around.

Coming from this insight, i teach the “three rules of performance optimization” to my students:

  1. Don’t
  2. Not Yet
  3. Measure

A little disclaimer: Performance optimizations are measured in milliseconds. You are still responsible for complexity optimizations and should engage them. Complexity is measured in O(n).

I blogged about the rules some time ago, so I won’t repeat the whole meaning behind them. Today, I want to tell a story related to rule three (“Measure”) and why it’s generally a good idea to stay clear of optimizations if not absolutely necessary.

An accidental observation

by ortodoxfoto / fotolia

In one of our long-running projects, we store data in a 24/7 manner since more than ten years. The project started on Pentium IV boxes with 120 GB harddisks. Soon enough, the available disk space vanished rapidely. Our customer wanted to optimize the storage efficiency. We told him that we can always trade storage space versus computation time or the other way around (the infamous space/time tradeoff), but if we compress the data in the system’s archive to save space, it will result in slower archive access. Our customer understood the tradeoff and decided he wanted storage efficiency over access speed for the archive.

So we added a compression step when certain data types were stored in the archive. Because the data was text based (XML and other formats), the compression rate was at 90% and even higher, meaning that we could fit ten times more data on the disk than before. We certainly met the customer’s goal of store efficiency. But what about the access speed? We needed to add the decompression step for certain data types at the place where our system loads from the archive. After that, we hoped that the speed didn’t suffer too badly. We measured the access times before and after the change and couldn’t believe our eyes: The access time was nearly ten times faster than before. There was no tradeoff, we actually shrank memory consumption and computation time at once and in the same ballpark figure. We felt like heros.

Discovering false premises

Why did this happen? Our explanation is that at some specific point in time, the CPUs became too fast for a tradeoff. In the good old days, there really was a tradeoff: if you needed to compress parts of your harddisk to save space, loading these parts became slower. Because the CPU had to perform extra work on top of the loading, you had to wait longer. Loading more data directly from disk was faster than loading less data from disk and decompressing it. When the CPU became fast enough to actually decompress during the I/O delay of the harddisk, that’s when the raw amount of data that needed to be transferred from disk determined the loading speed. And since uncompressed data is larger, it now took longer to load than compressed data.

At some specific point in time, the old wisdom that compressed data is slower became a lie. Nobody told us. We weren’t heros, we just lived on false premises.

Our customer was pleased and continued to be pleased for years. Every few years, the CPUs of the target machines would become even faster, but the harddisk performance would hardly improve. The new wisdom was truer than ever: Less data is faster, regardless of what the CPU has to do with it. This was a performance optimization that could be used everywhere. You want to increase I/O speed? Compress the data.

The tables begin to turn

Fast forward to modern days. A new technology promised to improve harddisk performance by orders of magnitude: The solid state disk (SSD) delivers impressive amounts of data per second, but more important, gets rid of the initial seek time that magnetic spindle disks had (those few milliseconds to locate the data on the disk that felt like ages for modern CPUs). We started our migration to SSD in 2010 and were SSD-exclusive at the end of 2013. Our customer was a bit more hesistant, but the latest generation of target machines run on SSDs, too. So how did this affect our performance optimization?

As you can probably deduce by now, the decompression work of the CPU re-emerged in the archive access time. It’s by no means as bad as in ancient times, but the days of “no tradeoff” are gone, again. The performance optimization isn’t an optimization anymore. We still have it in the system, because it was never meant to improve performance, but storage efficiency, and it still does that perfectly. And needs to, because SSD are still expensive and don’t offer storage space in abundance. But the old wisdom is back (partially): compressed data is slower, if not by much.

What do we learn from this?

Over the course of a few years, a specific feature (transparent storage compression) in our system was a performance burden, then a performance booster and a burden again. We didn’t change the code, we just changed the hardware circumstances. The best lesson to be learnt is that no performance optimization lasts forever. Premises will change. Effects will be negated. Bottlenecks will be shifted. It’s best to know when that happens. And then it’s best to be able to revoke the optimization. Or, if all this sounds way too much trouble for such a tiny performance gain, remember the first rule of performance optimization (Don’t) and just leave it alone. You can always tell yourself that you’ve just optimized your code for the machine it will run on in ten years.

Recap of the Schneide Dev Brunch 2015-12-13

If you couldn’t attend the Schneide Dev Brunch at 13th of December 2015, here is a summary of the main topics.

brunch64-borderedTwo weeks ago, we held another Schneide Dev Brunch, a regular brunch on the second sunday of every other (even) month, only that all attendees want to talk about software development and various other topics. So if you bring a software-related topic along with your food, everyone has something to share. The brunch was small this time, but with enough stuff to talk about. As usual, a lot of topics and chatter were exchanged. This recapitulation tries to highlight the main topics of the brunch, but cannot reiterate everything that was spoken. If you were there, you probably find this list inconclusive:

Company strategies

Our first topic was about the changes that happen in company culture once a certain threshold is overstepped. The founders lose touch with their own groundwork and then with their own employees. Compliance frameworks are installed and then enforced, even if the rules make no sense in specific cases. A new hierarchy layer, the middle management, springs into existence and is populated by people that never worked on the topic but make all the decisions. The brightest engineers are promoted to a management position and find themselves helpless and overburdened. Adopting a new technology or tool takes forever now. The whole company stalls technologically.

Sounds familiar? We discussed several cases of this dramaturgy and some ways around it. One possible remedy is to never grow big enough. Stay small, stay fast and stay agile. That’s the Schneide way.

Code analysis with jDeodorant

We devoted a lot of time on getting to know jDeodorant, an eclipse-based code smell detection tool for Java. We grabbed a real project and analyzed it with the tool. Well, this step alone took its time, because the plugin cannot be operated in an intuitive manner. It presents itself as a collection of student thesis work without overarching narrative and a clear disregard of expectation conformity. If several experienced eclipse users cannot figure out how a tool works despite having used similar tools for years, something is afoul. We got past the bad user experience by viewing several screencasts, the most noteworthy being a plain feature demonstration.

Once you figure out the handling, the tool helps you to find code smells or refactoring opportunities. In our case, most of the findings were false alarms or overly picky. But in two cases, the tool provided a clear hint on how to make the code better (both being feature envies). If the project would really benefit from the proposed refactorings is subject for discussion. The tool acts like a very assiduous colleague in a code review when every improvement gets rewarded.

We really don’t know how to rate this tool. It’s hard to learn and provides little value on first sight, but might be useful on larger legacy code bases. We’ll keep it at the back of our minds.

Naming and syntax rules

During the discussion about jDeodorant, we talked about naming schemes and other syntax rules. We remembered horrific conventions like prefixed I and E or suffixed Exception. The last one got some curious looks, because it’s still a convention in the Java SDK and some names won’t make it without, like the beloved IOException. But what about the NullPointerException? Wouldn’t NullPointer describe the problem just as good? Kevlin Henney already talked about this and other ineffective coding habits (if you have audio degradation halfway through, try another video of the talk). It’s a good eye-opener to (some of) the habits we’ve adopted without questioning them. But challenging the status quo is a good thing if done in reasonable doses and with a constructive attitude.

Unit testing

When we played around with jDeodorant and surfed the code of the project that served as our testing ground, the Infinitest widget raised some questions. So we talked about Continuous Testing, unit tests and some pitfalls if your tests aren’t blazing fast. The eclipse plugin for MoreUnit was mentioned soon. Those two plugins really make a difference in working with tests. Especially the unannounced shortcut Ctrl+J is very helpful. I’ve even blogged about the topic back in 2011.

Epilogue

As usual, the Dev Brunch contained a lot more chatter and talk than listed here. The number of attendees makes for an unique experience every time. We are looking forward to the next Dev Brunch at the Softwareschneiderei. And as always, we are open for guests and future regulars. Just drop us a notice and we’ll invite you over next time.

Our voyage to service separation – Part II

We transformed our evolutionary grown IT landscape to a planned setup. Here is what we learned on the way (part 2/2).

Recap of the situation

In the first part of this blog series, we introduced you to our evolutionary grown IT landscape. We had a room full of snow- flaked servers and no overall concept how to use them. We wanted our services to be self-contained and separated. So we chose the approach of virtualization to host one VM per service on a uniform platform. We chose VirtualBox, Vagrant and Ansible to help us along the way.
This blog entry tells you about the way and our experiences and insights.

The migration

In order to migrate every service you use to its own virtual machine (VM), you’ll need a list or map of your services first. We gathered our list, compared it to reality, adjusted it, reiterated everything, added the forgotten services, drew the map, compared again, drew again and even then missed some services that are painfully obvious in hindsight, like DNS or SMTP. We identified more than 15 distinct services and estimated their resource profile. Then we planned the VM layouts and estimated the required computation power to host all of them. Then we bought the servers.

We started with three powerful hosting servers but soon saw that there is a group of “alpha VMs” with elevated requirements on availability and bought a fourth hosting server with emphasis on redundancy. If some seldom used backoffice service goes down, that’s one thing. The most important services of our company should not go down because of a harddisk failure or such.

Four nearly identical hosting servers to run 15+ VMs on required a repeatable process to set things up. This is where the first tip comes into play:

  • Document everything. Document all the details. Have your Wiki ready and write a step-by-step tutorial for every task you perform. It’s really tedious and probably a bit cumbersome at first, but it will pay of sooner and better than you’d imagine.

We started the migration process with the least important services to get a feeling for the required steps. It turned out later that these services were also the most time-consuming ones. The most essential and seemingly complex services took the least time. We essentially experienced the pareto effect but in reverse: We started with the lowest benefit for the highest cost. But we can give two tips from this experience:

  • Go the extra mile. Just forget about the pareto effect and migrate all services. It’s so much more fun to have a clean IT landscape map than one where most things are tidy but there’s an area marked “here be dragons”.
  • Migration effort and service importance aren’t linked. Our most important service was migrated in about half an hour. Our least important service needed nearly three days. It’s all about the system architecture of the service and if it values self-containment.

The migration took place over the course of a few months with frequent address changes of our tools and an awful lot of communication for cutoff dates. If you need to migrate a service, be very open about the process and make sure that the old service address won’t work after the switch. I cannot count the amount of e-mails I wrote with the subject prefix “IMPORTANT!”. But the transition went smooth and without problems, so we probably added some extra caution that might not have been necessary.

After the migration

When we had migrated our last service in its own VM, there were a lot of old servers without any purpose anymore. We switched them off and got rid of them. Now we had nearly two dozen new servers to care for. One insight we had right after the start of our journey is that virtualized servers require the same amount of administration as physical ones. Just using our old approaches for the new IT landscape wouldn’t cut it. So we invested heavily in automation and scripted everything. Want to set up a new CI build slave? Just add its address into Ansible’s inventory and run the script (“playbook”). All servers need security updates? Just one command and a little wait.

Gears by Pete BirkinshawLearning to automate the administrative tasks in the right way had a steep curve, but it’s the only feasible way. We benefit heavily from the simple fact that we forced ourselves to do it by making it impossible to handle the tasks manually. It’s a “burned bridges” approach, but upon reaching the goal, it really pays off. So another tip:

  • Automate everything. Even if you think you’ll perform this task just a few times – that’s exactly the scenario to automate it to never have to bother with the details again. Automation is key if you want to scale your IT landscape to reasonable sizes.

Reaping the profit

We’ve done the migration and have a fully virtualized setup now. This would not be very beneficial in itself, but opens the door for another level of capabilities we simply couldn’t leverage before. Let me just describe two of them:

  • Rethink your backup strategy. With virtual machines, you can now backup your services on an appliance level. If you wanted to perform this with a real server, you would need to buy the exact same hardware, make exact copies of the harddisks and store this “clone machine” somewhere safe. Creating an appliance level backup means to stop the VM, export it and restart it. You’ll have some downtime, but everything else is just a (big) file.
  • Rethink your service maintainance strategy. We often performed test upgrades to newer versions of our important services on test machines. If the upgrade went well, we would perform it again on the live server and hope for the best. With virtual machines and appliance backups, you can try the upgrade on an exact copy of the live server over and over again. And if you are happy with the result, you just swap your copy with the live server and everything’s fine. No need for duplicated procedures, you always work with the real deal – well, an indistinguishable copy of it.

Conclusion

We’ve migrated our IT landscape from evoluationary to a planned virtualized state in just about a year. We’ve invested weeks of work in it, just to have the same services available as before. From a naive viewpoint, nothing much has changed. So – was it worth it?

The answer is short and clear: Absolutely yes. Even in the short time after the migration, the whole setup performs smoother and more in a planned way than just by chance. The layout can be communicated clearer and on different levels. And every virtual machine has its own use case, to the point and dedicated. We now have an IT landscape that obeys our rules and responds to our needs, whereas before we often needed to make hard compromises.

The positive effects of documentation and automation alone are worth the journey, even if they are mere side effects of the main goal. +1, would migrate again.

Our voyage to service separation – Part I

We transformed our evolutionary grown IT landscape to a planned setup. Here is what we learned on the way.

What you need to know

We are a small software development company with a home-grown IT infrastructure. The euphemism for such a state is “evolutionary grown”, denoting a process that was shaped by the most elementary forces, often implicitely. One such implicit force is laziness: If there is a quick way to do things, it will be done this way. Why invest effort if everything works just fine?
During an internal safety review, we identified our IT landscape as a risk factor. It was designed to meet yesterday’s and perhaps today’s demands, but in no way aligned to our strategic vision. We decided to invest in our IT to bring it to a planned state that we are confident will sustain our demands of tomorrow – or be easily adaptable.

Where we started

Our starting point was a room full of servers that were bought at some point to serve a specific need like “be the build box”. Every server started with a good reason to exist and evolved from there. Some gathered more and more services, some were repurposed and some idled along. We identified only two servers that were essential for the company: one was the continuous integration server master and one hosted nearly all mission-critical services at once. The latter server was also our oldest machine in production usage. It was secured against data loss, but not against outages. So everytime this server went down, our company essentially came to a stop because all services were offline. Luckily, it went down very infrequently, but it still identified as a clear single point of failure.

Where we wanted to go

containersIn April 2014, the heartbleed vulnerability was published. We luckily weren’t affected on a large scale, but took it as a wake-up call to review our IT setup and to develop a strategy to mitigate the effects of disasters similar in scope to heartbleed while we still have time. We wanted to have our IT in a condition where we actually choose which risks we take instead of just hoping for the best. So we sat before a whiteboard and outlined the goals: We wanted to separate and self-contain every essential service, so that the compromising or outage of one service doesn’t affect the others. That means one machine (or container) per service. To gain flexibility, we also planned to separate our IT landscape into two layers: The “metal layer” provides the computation power, while the “appliance layer” realizes the services. We wanted to be able to implement the appliance layer nearly independtly to the metal layer, which means to use some sort of virtualization. In modern words, we wanted to have a “cloud platform” to deploy our service applications on. We just don’t wanted it out on the internet but in our computer center. To sum up, we wanted to separate hardware and software and move every service in its own compartment.

What technologies we chose

We thought about fitting technology for a long time but settled for a small-scale, bottom-up approach: Start with just a few metal machines (hosts) and use a familiar virtualization product. In our case, this meant two standard servers, Linux and Oracle’s VirtualBox to run the virtual computers. There sure are more professional and powerful virtualization products out there, but we had years of experience (and sometimes frustration) with VirtualBox and didn’t want to rely on an unknown technology. It’s not exciting, but works well enough for our use case – and we knew that beforehands.
We decided against any fancy cloud or grid software to combine the hosts to a pool and just planned the hosting of the virtual machines (VMs) statically by hand. This might mean that one host gets bored while another host cannot handle the pressure anymore. It will be our responsibility to take that problem into account. This approach primarily achieves one thing: it keeps everything rather simple. Each host has a list of VMs and that’s it. If we want to migrate a VM to another host, we have to do it manually.
To create the VMs, we used Vagrant, which turned out fine for three-quarters of our machines, but proved toxic for the remaining ones. Vagrant is a very handy tool for developers to quickly launch a VM, but it makes a lot of assumptions that might not match your specific requirements. We essentially abandoned Vagrant after the initial phase.
During the migration phase of our services, we adopted another tool to solve the problem of scaling effects in maintainance. It’s another story to maintain 20+ servers instead of the handful we had beforehands. Luckily, Ansible proved useful to automate most of our normal administration tasks. This transition from manual to automated administration wasn’t part of the original plan, but is one of the biggest payoffs. But that’s stuff for the next blog entry.

What’s next?

In this first part of our story to regain control of our IT landscape, we described the starting point, the plan and the tools. In the next part, you’ll hear about the migration and where we ended up. We will also point out our experiences along the way and hopefully give some useful tips if you think of reshaping your services, too: Click here to read part two of the series.

My motto: Make it visible

To have a clear principle that guides your actions and inventions is a very powerful thing. In this short blog entry, I describe my principle of making information visible.

Nearly ten years ago, I read the wonderful book “Behind Closed Doors. Secrets of Great Management” by Johanna Rothman and Esther Derby. They shared a lot of valuable insights and tipps for my management career, but more important, gave a name to a trend I was pursuing much longer. In their book, they introduce the central aspect of the “Big Visible Chart”, a whiteboard that contains all the important work. This term combined several lines of thought that lingered in my head at the time without myself being able to fully express them. Let me reiterate some of them:

  • Extreme Feedback Devices (XFD) were a new concept back in the days. The aspect of physical interaction with a purely virtual software project thrilled me. Given a sensible choice of the feedback device, it represents project state in a intuitive manner.
  • Scrum and Kanban Boards got popular around the same time. I always rationally regarded them as poor man’s issue tracker, but the ability to really move things around instead of just clicking had something in itself.
  • My father always mentioned his Project Cockpit that he used in his company to maintain an overview of all upcoming and present projects. This cockpit is essentially a Scrum Board on project granularity. We use our variation with great success.
  • A lot of small everyday aspects required my attention much too often. Things like if the dishwasher in a shared appartment contains dirty or clean dishes always needed careful examination.

It was about time to weave all these motivations into one overarching motto that could guide my progress. The “Big Visible Chart” was the first step to this motto, but not the last. A big chart is really just a big information radiator and totally unsuited for the dishwasher use case. The motto needed to contain even more than “put all information on a central whiteboard”. I wasn’t able to word my motto until Bret Victor came along and held his talk “Inventing On Principle” (if you don’t know it, go and watch it now, I’ll be waiting). He talks about the personal mission statement that you should find to arrange your actions around it. That was the magical moment when everything fell into place for me. I knew my motto all along, but couldn’t spell it. And then, it was clear: “Make it visible”. My personal mission is to make things visible.

Let me try to give you a few examples where I applied my principle of making information visible:

  • I built a lot of Extreme Feedback Devices that range from single lamps over multi-colored displays to speech synthesis and even a little waterfall that gets switched on if things are “in a state of flux”, like being built on the CI server. All the devices are clearly perceivable and express information that would otherwise need to be actively pulled from different sources. I even wrote a book chapter about this topic and talk about it on conferences.
  • A lot of recurring tasks in my team are handled by paper tokens that get passed on when the job is done. Examples are the blog token (yes, it’s currently on my desk) for blog entries or the backup token as a reminder to bring in the remotely stored backup device and sync it. These tokens not only remind the next owner of his duty, but also act as a sign that you’ve accomplished your job, just like with task cards on the Scrum board.
  • If we need to work directly on a client server, we put on our “live server hat“ so that we are reminded to be extra careful (in german, there’s the idiom of “auf der hut sein”). But the hat is also a plain visible sign to everybody else to be a tad more silent and refrain from disturbing. Don’t talk to the hat! A lesser grade of “do not disturb” sign is the fully applied headphone.
  • Of course I built my own variation of my father’s Project Cockpit. It’s a great tracking device to never forget about any project, how sparse the actual activity might be.
  • And I solved the dishwasher case: The last action when clearing the dishes should be to already apply the next dishwasher tab. That way, whenever you open the dishwasher door, there are two possible states: if the tab case is empty, the dishes are clean (or somebody forgot to re-arm). If the tab is closed, you can be sure to have dirty dishes in the machine. The case gets re-opened during the next washing cycle.
  • An extra example might be the date of opening we write on the milk and juice cartons so you’ll know how long it has been open already.

All of these examples make information visible in place that would otherwise require you to collect it by sampling, measuring or asking around. Information radiators are typically big objects that typically do that job for you and present you the result. I’ve come to find that information radiators can be as little as a dishwasher tab in the right spot. The important aspect is to think about a way to make the information visible without much effort.

So if you repeatedly invest effort to gather all necessary data for an information, ask yourself: how could you automate or just formalize things so that you don’t have to gather the data, but have the information right before your eyes whenever you need it? It’s as simple as a little indicator on your mailbox that gets raised by the mailman or as complicated as a multi-colored LED in your faucet indicating the water temperature. The overarching principle is always to make information visible. It’s a very powerful motto to live by.